The price, up front
Here is the entire Claude Mythos 5.1 rate card. Every number below also applies, to the penny, to Fable 5.1, a point I will come back to.
| Meter | Price (per million tokens) | Notes |
|---|---|---|
| Base input | $10.00 | Unchanged from Fable 5 |
| Base output | $50.00 | Unchanged from Fable 5 |
| Batch input | $5.00 | 50% off, Message Batches API |
| Batch output | $25.00 | 50% off |
| Cache write (5-minute) | $12.50 | 1.25x base input |
| Cache write (1-hour) | $20.00 | 2x base input |
| Cache read | $0.25 | 2.5% of base input, the headline change |
The specs behind those numbers are worth stating so you can size a bill: 1M-token context, 128K max output, adaptive thinking that is always on, a default high effort setting, and a June 2026 knowledge cutoff. Mythos 5.1 runs on the Claude API, Amazon Bedrock, Google Cloud, and Microsoft Foundry, and those platforms set their own regional rates on top.
Notice what is not here: no per-seat fee, no monthly minimum, no plan tiers. This is raw model pricing billed per token, so your real cost is a function of how much text goes in, how much comes out, and how much of the input you can serve from cache. That last variable is the whole game this release.
The cache read is the actual news
Every other current Claude model prices a cache hit at 10% of its base input rate. Mythos 5.1 and Fable 5.1 price it at 2.5%. On a $10 input model, that is $0.25 per million tokens instead of $1.00.
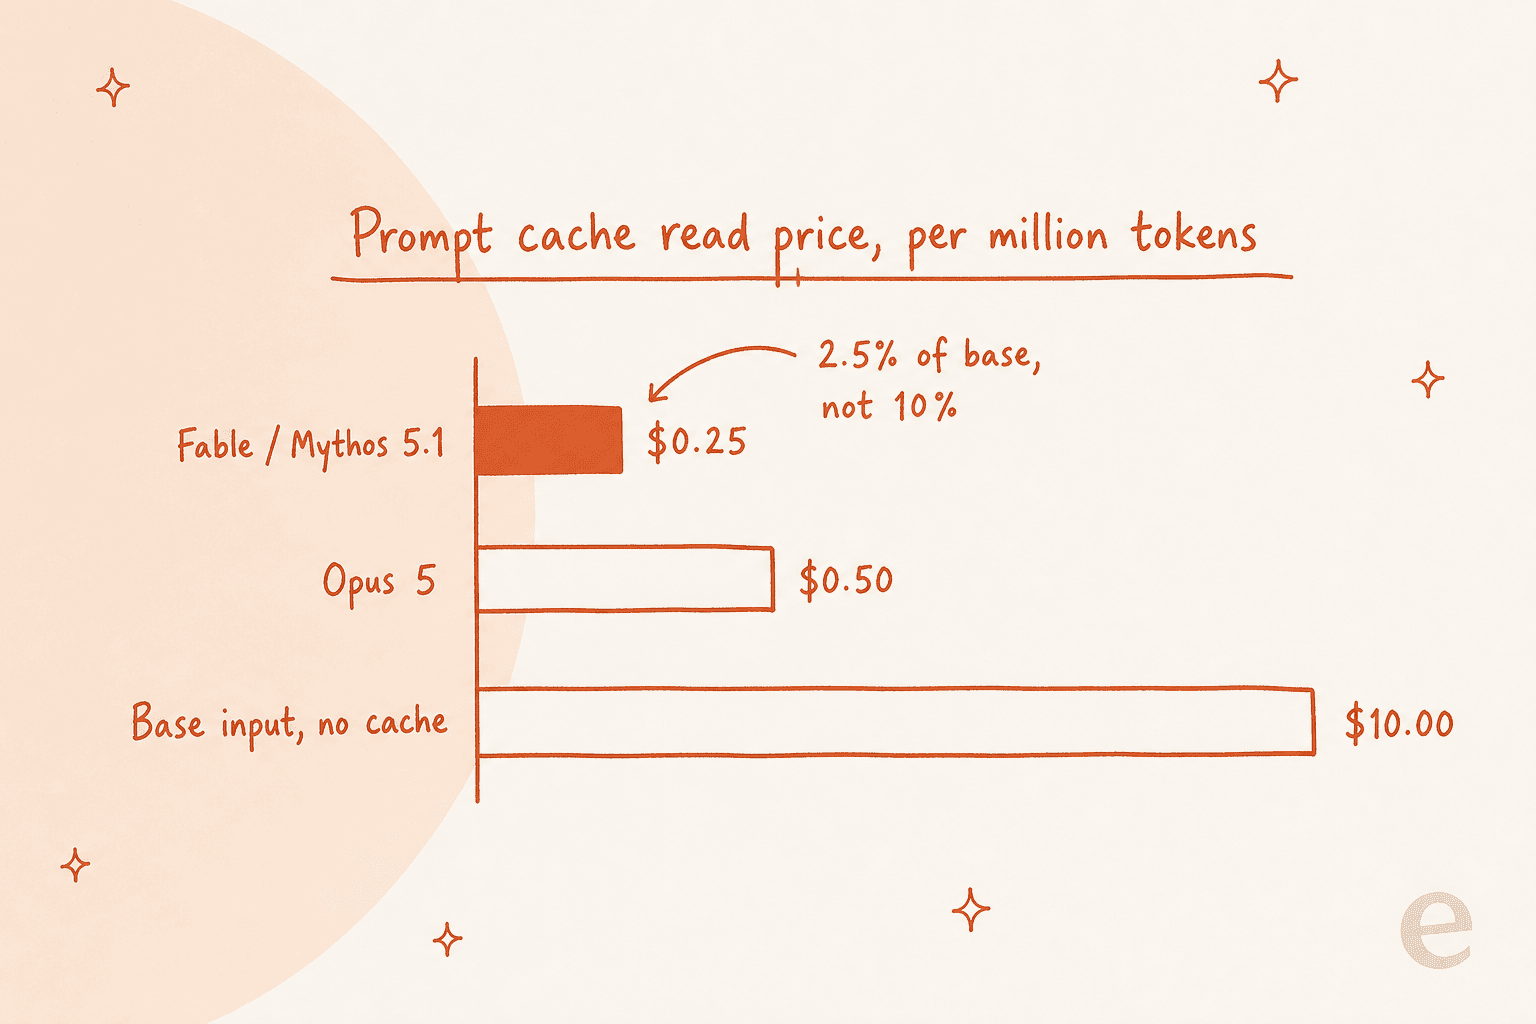
The number that makes people do a double-take: a Mythos 5.1 cache read is half the price of an Opus 5 cache read ($0.25 vs $0.50), even though Mythos costs twice as much per base input token. Anthropic is effectively saying: the expensive part is thinking about new tokens, and re-reading tokens it has already processed should be nearly free.
That matters because of where the tokens go in a real agent. A coding CLI or a long-running support agent re-sends its entire transcript on every turn. Turn 20 might carry a million tokens of context, almost all of it a cache hit. When the cache read falls 4x, the dominant line item on that kind of bill falls with it. As Simon Willison put it on Hacker News:
"Bit of a discount if you're using caching... This should impact any long-running agent since subsequent calls can benefit from cached reads for previous transcripts."
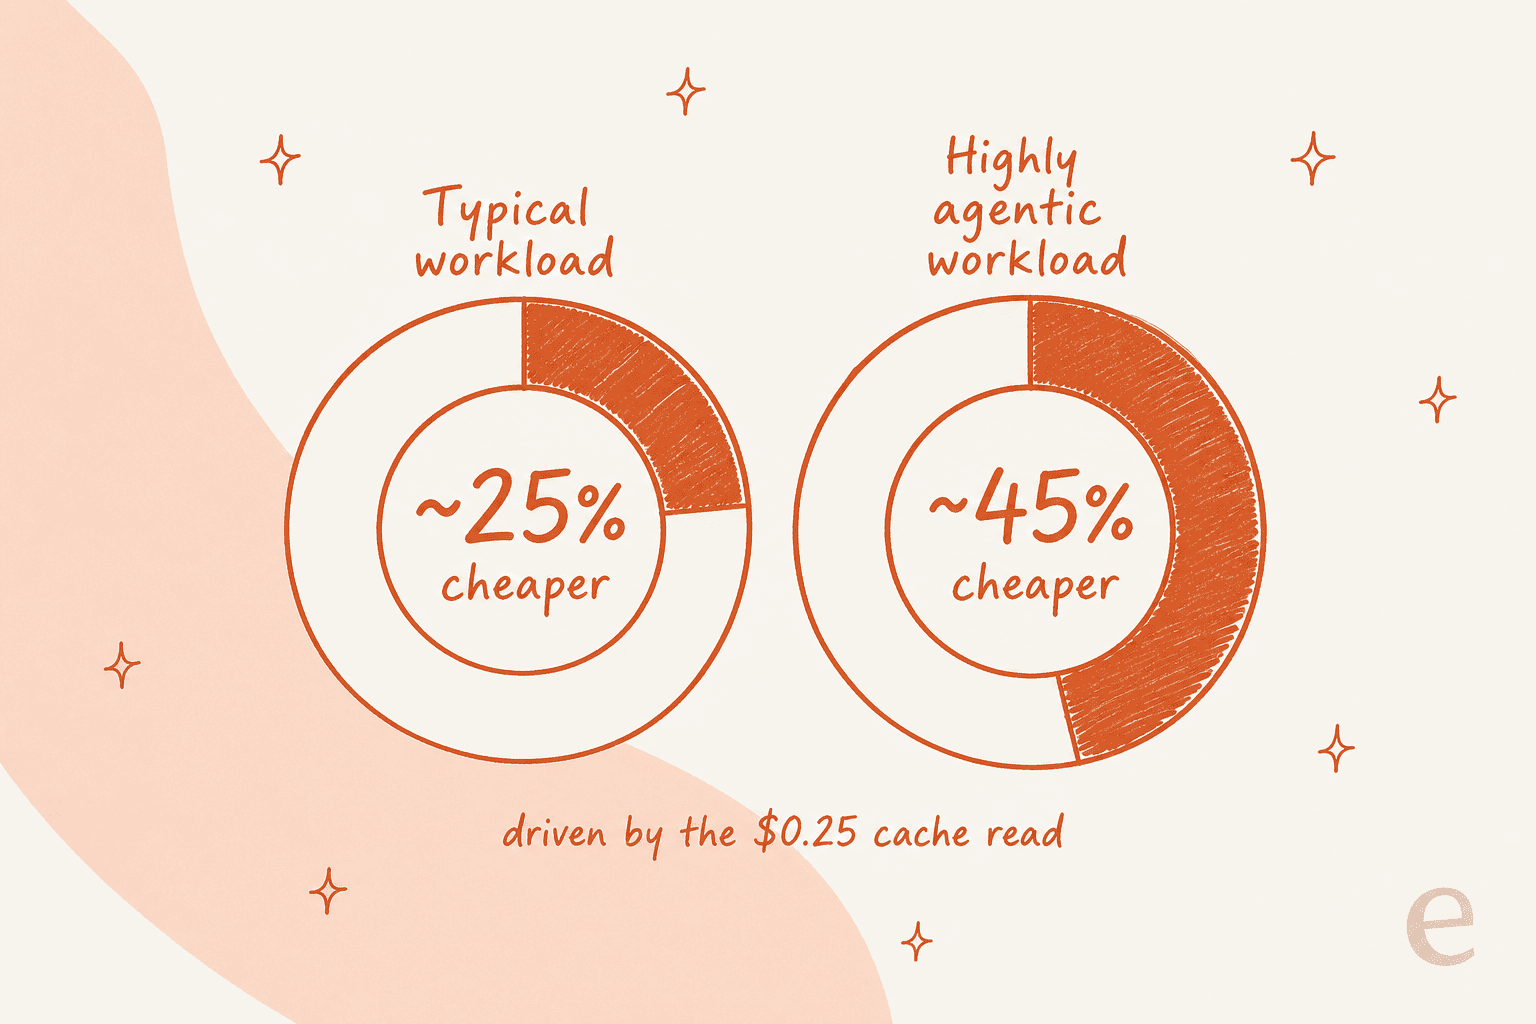
Anthropic put real figures on it after measuring four weeks of August 2026 usage: about 25% cheaper for typical workloads, and up to roughly 45% cheaper for highly agentic ones. The split is entirely down to how cache-heavy the work is.
Here is the honest counterweight, because a pricing post owes you the skeptics too. The cheaper cache read only bites if cache reads are a big share of your spend. Output tokens are still $50 per million and did not move. One Hacker News commenter, fastball, worked a 20-turn example: a conversation ending at 1M tokens of context came to $72.00 on Fable 5 and $64.88 on Fable 5.1, because the $50 of output tokens was identical on both. Cheaper, but not the 25% you might expect if you skim the headline. And another user was blunter: "This is just cache reads. In real usage it costs 15% more than Fable 5." The lesson is to run your own token mix through the math, not to assume the top-line percentage is yours.
To make that easy, plug your own numbers in:
Mythos and Fable cost the same because they are the same model
This is the fact that reframes the whole pricing question. Mythos 5.1 and Fable 5.1 are the same underlying model, with the same weights. The only difference is the safeguard layer: Fable 5.1 is benchmarked with production safeguards on, and when a safeguard fires it hands the task to a different model. Mythos 5.1 runs without that intervention.
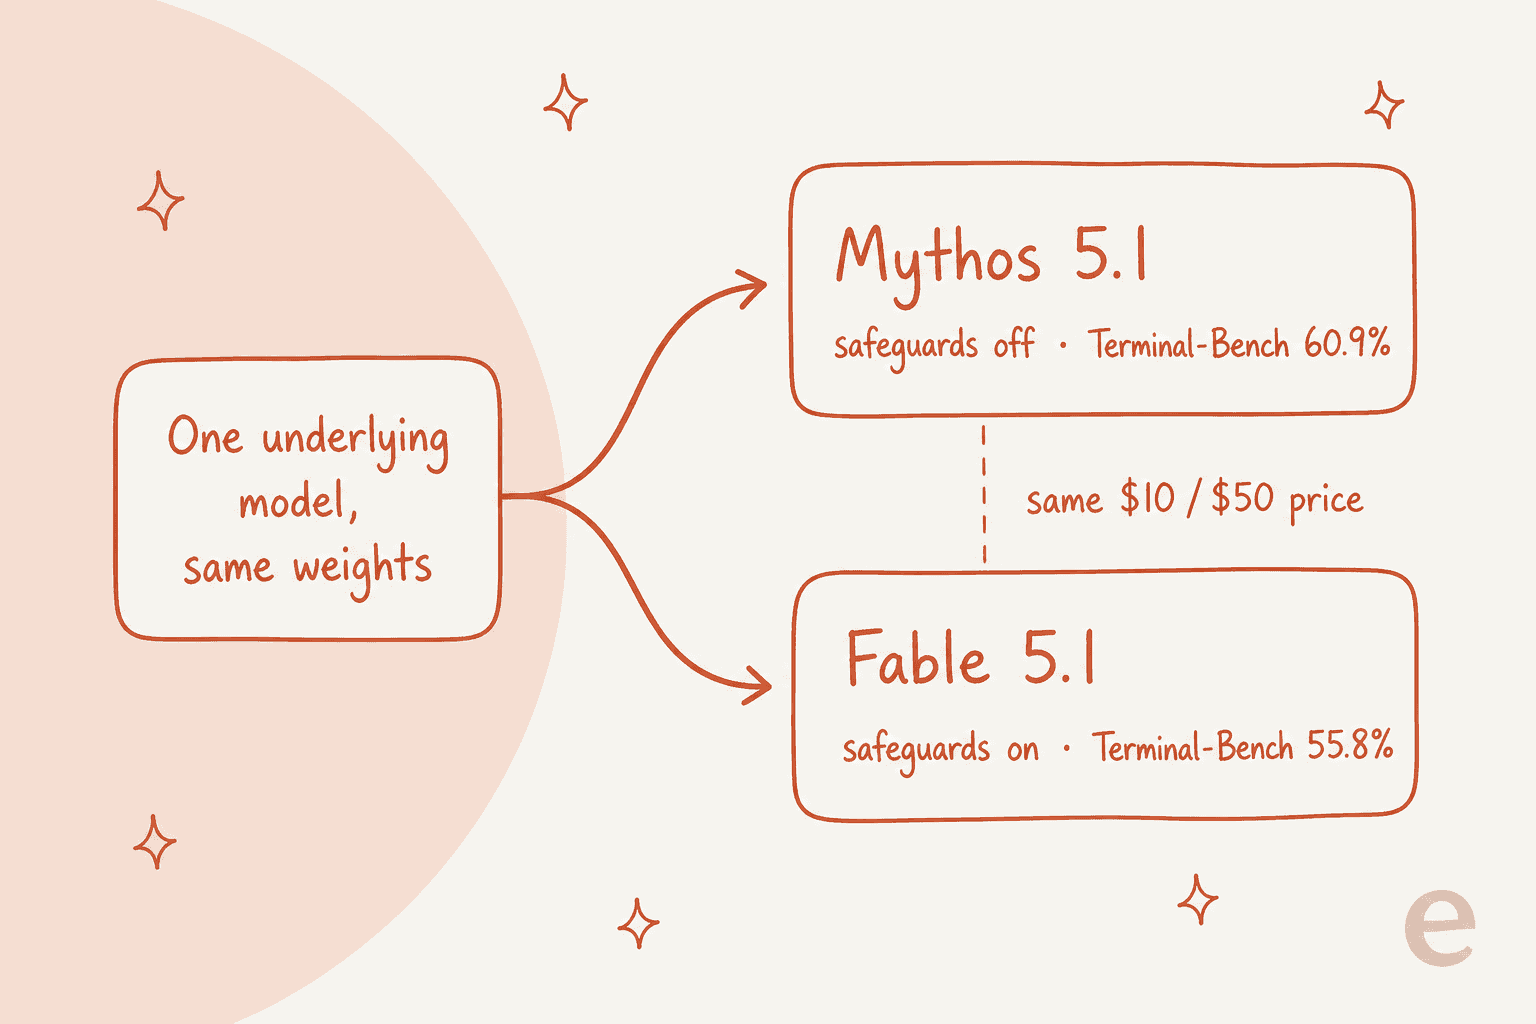
So when you see Mythos 5.1 score 60.9% on Terminal-Bench 4.0 against Fable 5.1's 55.8%, that gap is not a smarter model. It is the tax the safeguards charge when they intervene and route a task away. Anthropic expects the gap to shrink as the safeguards get more precise. Pricing them identically is the honest move, because you are paying for the same weights either way.
That also explains why the base rate did not fall even though this is a point release. On Hacker News, GodelNumbering read the cache-read cut as a demand signal rather than a generosity one:
"This gives a lot of credit to the theory that Anthropic did not get much bite on Fable at its original pricing, which in turn likely places a ceiling on LLM pricing in general."
Whether or not that read is right, the practical takeaway for a buyer is clean: you are not choosing between two price points. You are choosing between two safeguard configurations at one price point.
The pricing you plan around is Fable's, because you cannot run Mythos
Here is the part most pricing write-ups skip. A number on a rate card is only real if you can call the model. For Mythos 5.1, most teams cannot.
Access is US-scoped today, and it comes through one of three doors: Anthropic's Cyber Verification Program (where Mythos access is promised "in the near future" but is not live yet), the Life Sciences Verification Program (an invite-only beta built with the US government), or a direct conversation with your Anthropic, AWS, or Google Cloud account team. On top of that, using Mythos 5.1 requires accepting 30-day data retention by default, which is its own line in a procurement review.
For everyone else, the model you can actually put in production is Fable 5.1, available on the Claude API, Bedrock, Google Cloud, and Foundry with no verification gate. And since it is the same weights, "which one is the better value" is the wrong question. You buy Fable 5.1, you plan around the Fable 5.1 price, and the two rate cards being identical means you lose nothing by not having Mythos access. The Mythos rate card is best read as confirmation of what you will pay for Fable, not as a separate thing to shop for.
Three API changes that touch your bill and your workflow
Pricing is not just the per-token rate, it is what your integration has to do to hit that rate. Three breaking API changes ship with this generation and apply to Fable 5.1 too, so factor them into any migration:
- Forced tool use now returns an error. If your agent relied on forcing a specific tool call, that pattern breaks and you will need to rework the tool-use flow.
- Thinking blocks are tied to the model that produced them. You cannot freely replay a thinking transcript from another model.
- New API accounts cannot edit prior context while preserving the thinking transcript. This is an anti-distillation measure, and it changes how you can structure long agent loops.
None of these change the sticker price, but they can change engineering time, which is the real total cost of ownership on any model migration. Budget for the rework, not just the tokens.
How it stacks against the rest of the lineup
Put Mythos 5.1 next to the models you would realistically weigh it against, and the picture is less "premium tier, premium price" than the base rate suggests, once caching is in play.
| Model | Input / output (per M) | Cache read (per M) | Context |
|---|---|---|---|
| Mythos 5.1 / Fable 5.1 | $10 / $50 | $0.25 | 1M |
| Opus 5 | $5 / $25 | $0.50 | 1M |
| Sonnet 5 | $2 / $10 | $0.20 | 1M |
| Haiku 4.5 | $1 / $5 | $0.10 | 200K |
Opus 5 is half the base price, but its cache read is double. So on a workload that is mostly cache hits, the effective gap between Opus 5 and Mythos/Fable 5.1 narrows sharply, which is exactly the case Anthropic is optimizing for. For a workload that is mostly fresh input and output, Opus 5 stays clearly cheaper. There is no single "cheaper model" answer, which is why the calculator above matters more than any leaderboard.
Worth naming the elephant, since the Hacker News thread did: cheaper open and Chinese models now price cache reads in single-digit cents, and several commenters argued that puts a ceiling on what frontier labs can charge. Mythos 5.1 pricing is a response to that pressure, not immunity from it.
Try eesel
If you are reading a model pricing page, you are usually trying to answer a downstream question: what will it cost to actually get support tickets resolved or content written. That is a different question from "what is the per-token rate," and it is the one eesel is built to answer.
The model is infrastructure. eesel is the employee you hire on top of it. You do not provision Mythos or Fable, count cache reads, or reserve capacity. You bring on a ready-to-work AI teammate for a specific job, and today the roster is an AI helpdesk teammate that joins your existing support queue and an AI blog writer. Each arrives with the skills, integrations, and company context for its role, and the price is a fixed monthly credit plan (1 credit per ticket or chat, from $299 a month for 500 credits), not per token, so a bill you can forecast replaces the token math on this page.
And because engineers ask: eesel is drivable from the eesel CLI, so the same teammate you configure in the dashboard can be operated from a terminal, automated in scripts, or driven by a coding agent like Claude Code, Codex, or Cursor. If your interest in Mythos 5.1 pricing was really about wiring a model into a support or content workflow, that is the layer that turns a raw model into work that gets done. It is free to try.