GPT-6 Luna API pricing: the standard tier
Here is the number most people came for. On the API pricing page, GPT-6 Luna standard pricing is $0.10 per million input tokens and $0.50 per million output tokens. Cached input drops to $0.01, and cache writes are $0.125 per million.
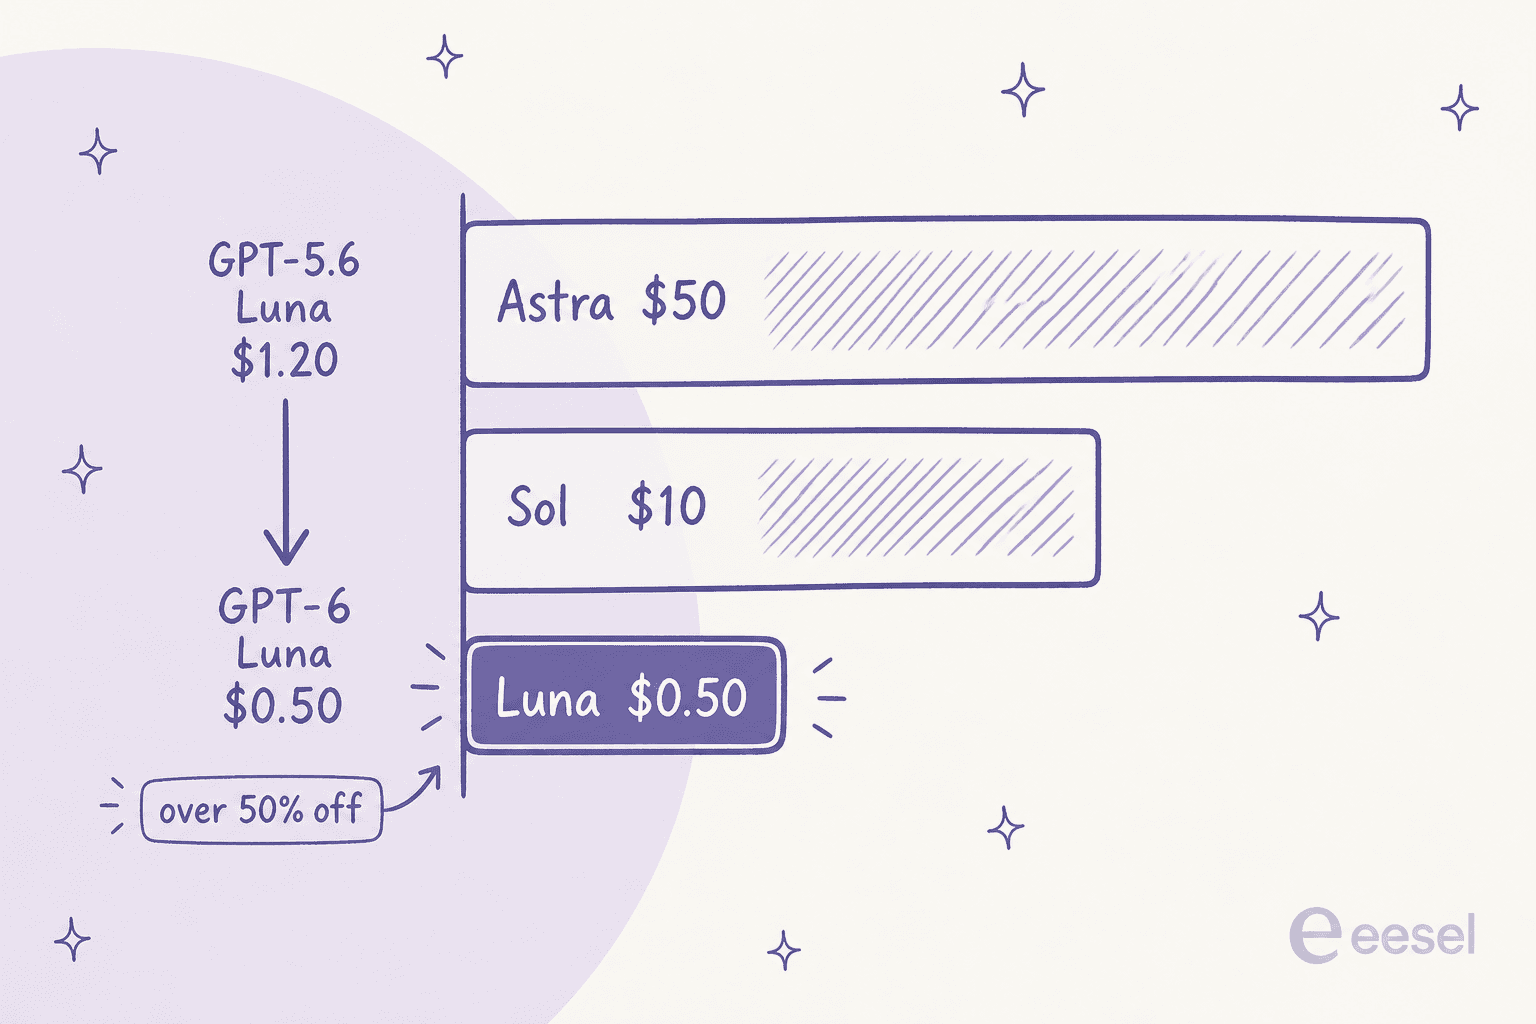
That puts Luna at the bottom of the OpenAI model lineup: far below the mid-tier Sol, and a rounding error next to the Astra flagship. Here is where the GPT-6 family sits on the standard, short-context tier, with the outgoing GPT-5.6 Luna for reference:
| Model | Input (per 1M) | Cached input | Output (per 1M) | Position |
|---|---|---|---|---|
| gpt-6-astra | $10.00 | $1.00 | $50.00 | Flagship |
| gpt-6-sol | $2.00 | $0.20 | $10.00 | Mid tier |
| gpt-6-luna | $0.10 | $0.01 | $0.50 | Cheapest (new) |
| gpt-5.6-luna | $0.20 | $0.02 | $1.20 | Prior light tier |
Source: OpenAI API pricing. The story the table tells is simple: GPT-6 Luna is the old GPT-5.6 Luna, with input halved and output cut by well over half. OpenRouter confirmed the family's rates on launch day. OpenAI's own framing on the launch post is "Build with Sol. Scale with Luna," which tells you exactly where Luna is meant to sit: the model you point at high-volume, simpler work.
The price cut: what changed, and what did not
A price cut this size usually comes with a capability story. This one mostly does not, and that is worth being honest about.
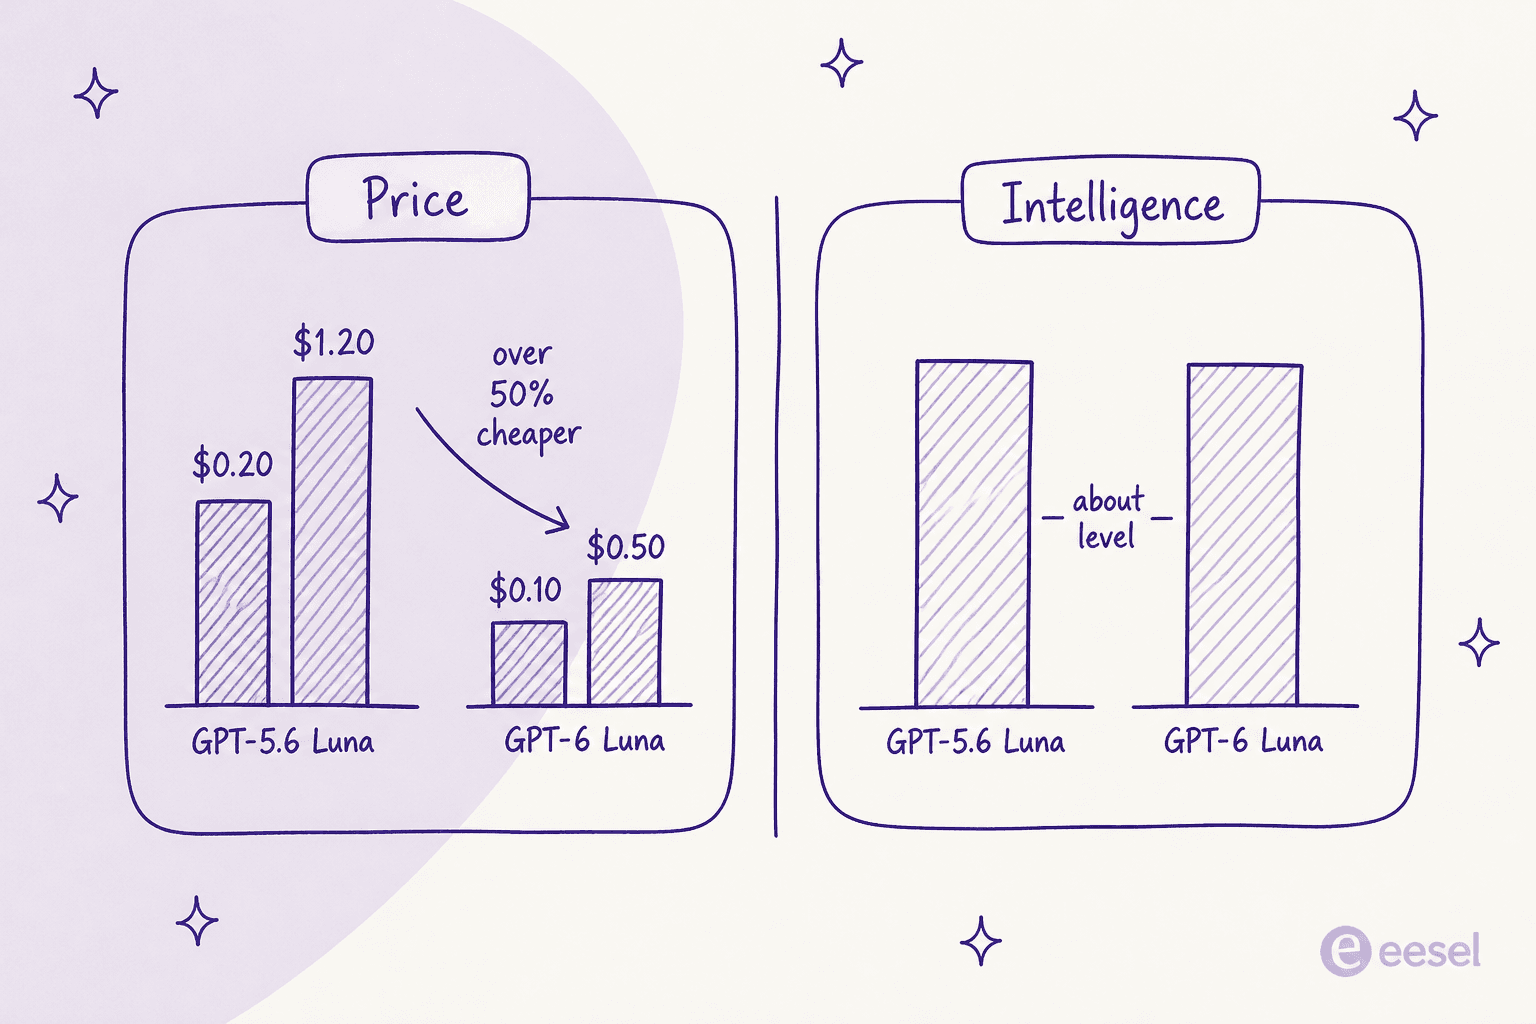
On the raw intelligence measure, Artificial Analysis reported that GPT-6 Sol and Luna "push the cost efficiency frontier by halving cost," while the Intelligence Index and Coding Agent Index "remain level with GPT-5.6, with progress in some evaluations and regressions in others." So the map is: the price moved a lot, the intelligence barely moved.
Where Luna did improve is reliability, and OpenAI leaned on it:
- Factuality. OpenAI reports the GPT-6 family makes fewer factual mistakes than its GPT-5.6 predecessors. Artificial Analysis logged Luna's max-effort hallucination rate dropping from 93% to 77%, a real improvement, though still higher than Sol's on the same test.
- Cost efficiency frontier. The point of Luna is throughput per dollar, and this is where it moves: the same lightweight intelligence at roughly half the token cost.
- Agentic evals. The family posted small gains across AutomationBench and Terminal-Bench, but Luna is not the model you reach for on hard agentic work. That is Sol and Astra.
The community read it the same way. On the launch discussion, one developer put the trade plainly:
"I'd have loved improved performance for 2x the price than ~equal performance for 0.5x the price."
That is the honest frame for GPT-6 Luna pricing. If you already ran GPT-5.6 Luna, this is a bill cut you get for free. If you were hoping the "6" meant a step change in raw smarts, the benchmark scores say to temper that.
Service tiers: the 4x swing most people miss
The standard rate is a starting point, not the whole story. GPT-6 Luna runs on the same service tiers as the rest of the family, and the gap between the cheapest and most expensive is 4x for the exact same model. For a high-volume model like Luna, that is the single biggest lever on cost.
| Tier | Input (per 1M) | Cached input | Output (per 1M) | Trade-off |
|---|---|---|---|---|
| Batch | $0.05 | $0.005 | $0.25 | 50% off, async, up to 24h |
| Flex | $0.05 | $0.005 | $0.25 | 50% off, slower, may queue |
| Standard | $0.10 | $0.01 | $0.50 | Default latency |
| Fast mode | $0.20 | $0.02 | $1.00 | 2x, lowest latency |
Source: OpenAI API pricing. A few things to know before you pick one:
- Batch and Flex are the same price, but different jobs. Batch is for asynchronous work you submit and collect later; Flex is for interactive requests you are willing to let run slower or queue. Both halve your bill.
- Fast mode doubles the rate for the lowest latency, and it accepts either
service_tier: "priority"orservice_tier: "fast". - Fast mode has a regional catch. For EU data residency it can fall back to standard, so do not assume it everywhere.
If a workload tolerates latency, defaulting it to Batch or Flex cuts your Luna spend in half again. That stacks with the price drop from GPT-5.6: a batchable job on GPT-6 Luna runs at $0.05/$0.25, which is where the truly cheap, high-volume classification and extraction jobs live.
The gotchas: long context and the spec
Two details hide in the model page fine print, and both can quietly reshape a budget.
First, long context is billed at a higher rate for the whole request. Luna's context window is a large 1,050,000 tokens, but any prompt over 272K input tokens flips the entire request to the long-context rate: $0.20 per million input and $0.75 per million output on the standard tier. That is 2x input and 1.5x output, applied to every token in the request, not just the ones past the threshold.
| Standard tier | Short context (≤272K) | Long context (>272K) |
|---|---|---|
| Input (per 1M) | $0.10 | $0.20 |
| Cached input | $0.01 | $0.02 |
| Output (per 1M) | $0.50 | $0.75 |
Second, the spec is worth knowing before you commit. GPT-6 Luna takes up to 922,000 input tokens and returns up to 128,000, with a knowledge cutoff of 18 May 2026, a month later than Sol's. It accepts text and image in, text out, and exposes reasoning effort from none all the way to max, with medium as the default. It also ships the full Responses API tool set: web search, code interpreter, hosted shell, computer use, and MCP. The rate-limit floor is Tier 1 at 500 requests and 500K tokens per minute, scaling to 30,000 requests and 180M tokens per minute at Tier 5.
Estimate your GPT-6 Luna API bill
Sticker prices are abstract until you put your own numbers in. Plug in the millions of input and output tokens you expect per month, pick a service tier, and this works out the monthly cost. It accounts for the long-context surcharge automatically.
The pattern most teams find is that output tokens dominate the bill, since output is 5x the input rate. For Luna's high-volume workloads that math scales fast, and moving a batch-friendly job to Batch is where the savings pay off fastest.
GPT-6 Luna pricing in ChatGPT and Codex
If you are not calling the API, GPT-6 Luna reaches you through ChatGPT and Codex, and this is where Luna's story is different from the rest of the family: it is the one everyone gets.
| Plan | Price | GPT-6 Luna access |
|---|---|---|
| Free | $0 | Yes (desktop app) |
| Go | $8/mo | Yes (desktop app) |
| Plus | $20/mo | Yes |
| Pro | From $100/mo | Yes |
| Business / Enterprise / Edu | Per seat | Yes |
Source: OpenAI launch announcement. A few things stand out:
- Luna reaches Free. This is the headline for non-developers: the Free plan and the $8 Go plan get GPT-6 Luna in the desktop app. Neither includes Sol, which starts at the $20/month Plus plan. If you have used a GPT-6 model without paying for ChatGPT, it was Luna.
- Paid plans stack Sol on top. Plus and up keep Luna and add GPT-6 Sol, so paying more does not take Luna away; it widens your model menu.
- Codex gets Luna too. OpenAI shipped both models into Codex at the same tiers, so coding-agent users can select Luna for cheaper, lighter runs.
Not everyone was convinced the subscription savings match the API cut. One developer noted that message-limit changes suggested the 50% API cut translated to something closer to a one-third cut inside the ChatGPT plans, so check your own allowance rather than assuming the sticker discount flows straight through.
How GPT-6 Luna pricing compares
Zooming out, where does Luna sit against the rest of the frontier? The short version is that OpenAI used Luna to set the floor on price for a properly useful model.
- Versus its own lineup: at $0.10/$0.50, Luna is one fifth the price of GPT-6 Sol ($2/$10) and one hundredth of GPT-6 Astra on output ($50). For high-volume, simpler work, Luna is the obvious pick; for hard reasoning or long-horizon agentic work, you move up to Sol or Astra.
- Versus Anthropic: Luna undercuts the light end of Anthropic's lineup sharply on raw token price, which is exactly the positioning OpenAI wanted at the bottom of the market.
- Versus Google: it competes head to head with Gemini's lightest options like Gemini 3 Flash on a price-for-intelligence basis, which is the real fight at this tier.
The bigger picture on the launch thread was that closed models keep getting cheaper without getting much smarter, which several developers framed as a race to the bottom on price. That is good news if you are buying tokens. It is a reminder, though, that a cheaper model does not change the harder part of shipping AI into a real workflow, which is everything around the model.
What GPT-6 Luna pricing means if you run a support team
Here is where I want to be useful rather than just tally rates. I build eesel's product, so I spend my time on how these models actually get wired into a live workflow, and the honest answer is a little counterintuitive.
If you run customer support or internal ops, a cheaper frontier model changes less than the headline suggests. A raw model like Luna is infrastructure. It is a capable, cheap engine, but out of the box it does not know your refund policy, it cannot see your last 50,000 tickets, it has no access to your order system, and it has no safe way to be tested against your real queue before it starts replying to customers. It is billed per token for thinking, not per problem solved. A rock-bottom token price is real, but it is a discount on the cheapest part of the project.
The unit that actually matters for a support team is cost per ticket, not cost per token. A token bill is unpredictable: it moves with prompt length, retries, and how chatty the model is on any given day. Across years of putting AI on live support queues, we have watched confident-sounding bots quietly give wrong answers, which is exactly why every rollout should be simulated against your own historical tickets before it goes near a customer. That is the gap between a model and a system built around it: your knowledge, your integrations, safe actions, and a way to test it on your history first.
This is also why I would not re-platform your support automation the week a new model ships. The best AI helpdesk agents and customer service tools are model-flexible by design, so when a cheaper or smarter model lands, you inherit the upgrade without rebuilding anything, and without renegotiating your budget around a new token rate.
Try eesel
If your interest in Luna's price is really "what will an AI cost me to actually resolve tickets," that is the job an AI teammate is built for, and it is where eesel sits. GPT-6 Luna is the engine; eesel is the employee you hire to drive it. The AI helpdesk agent trains on your past tickets and help center, plugs into the helpdesk you already run instead of replacing it, and lets you simulate it against thousands of your real historical tickets so you see how it will perform, and what it will cost, before it ever touches a live conversation.
The billing tells the story a token rate cannot. Instead of paying per token to think, you pay from $299/month for 500 credits (1 credit per ticket or chat), however long each ticket runs, with no per-seat fees, so the cost tracks outcomes rather than model chatter. You can start free with 100 credits and no card.
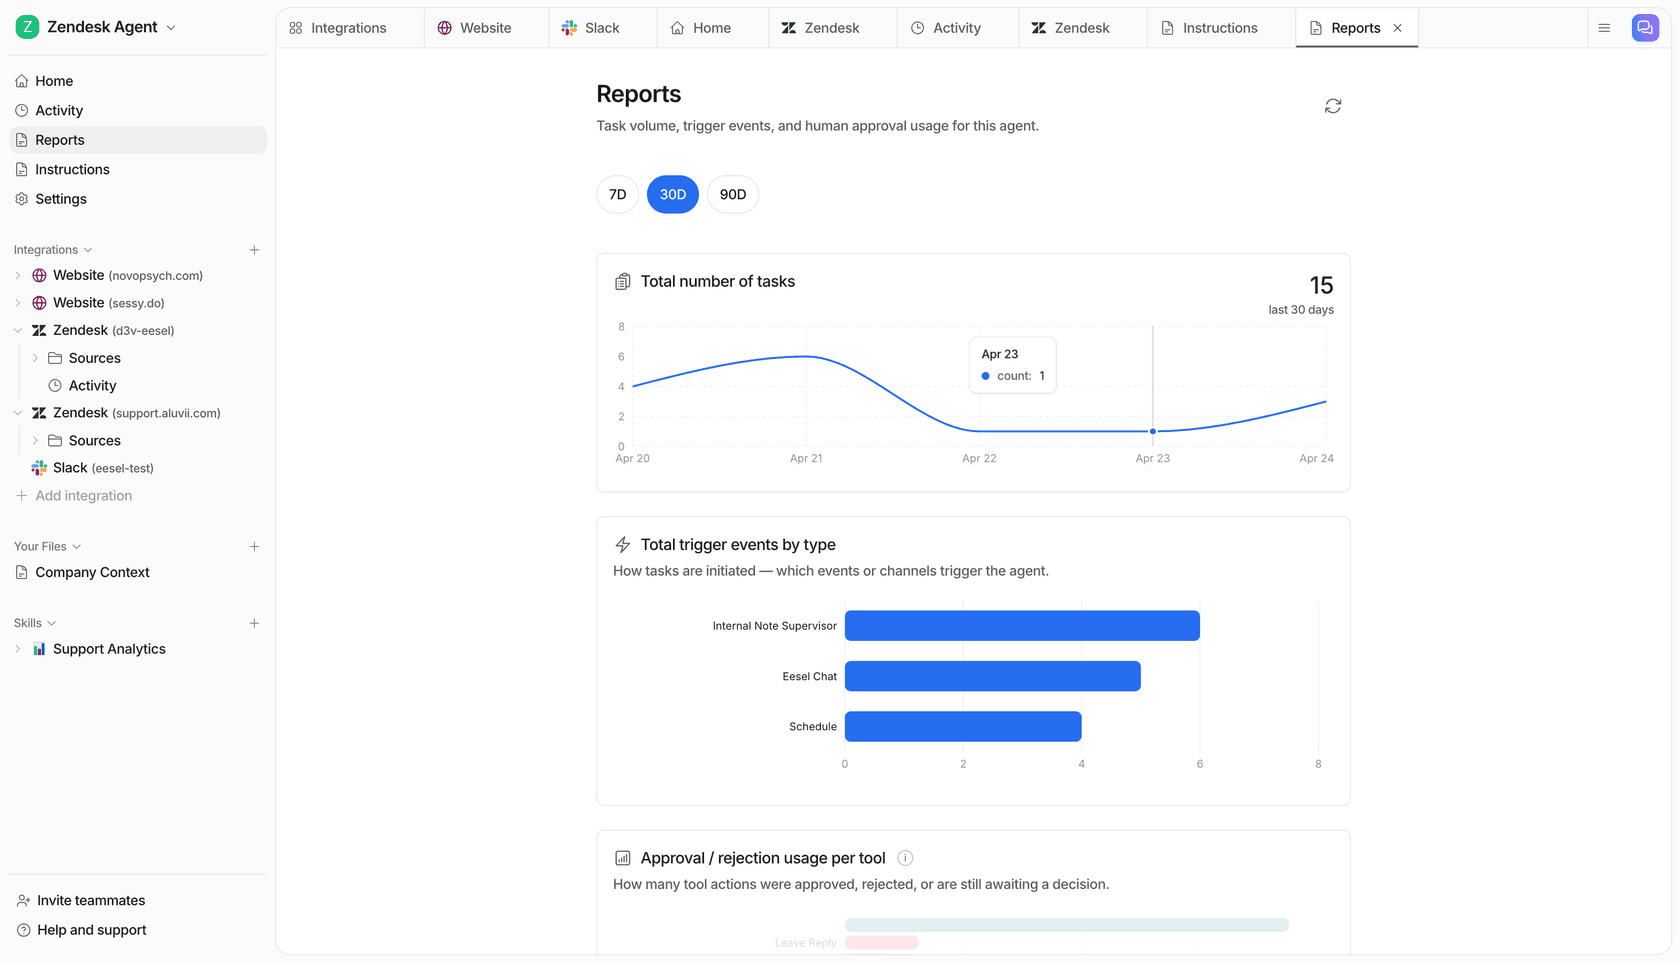
And because this is a developer-facing pricing question, it is worth knowing the whole eesel workspace is drivable from the terminal, not just a dashboard. The eesel CLI (npx @eesel/cli) lets a person, a script, or a coding agent like Claude Code, Codex, or Cursor operate the same teammate: connect a helpdesk, read and edit the standing instructions, run eesel activity to inspect past runs, and gate changes behind eesel approvals. Every command prints JSON, and --dry-run shows the exact server call a write would make before it sends. So the same credit-based plan you would model is something you can wire into your own tooling, not just click through in a UI.
GPT-6 Luna pricing is the cheapest way to run a capable model right now, and for high-volume, simple work the price is worth taking. But for most support teams, the token rate was never the number that mattered. Getting a tested, connected, accountable teammate into your existing workflow, on a fixed monthly plan, is the part worth spending your budget on.