Meta Muse Spark 1.1 pricing, the full rate card
Meta publishes this in two places and the two of them agree, which is not always how it goes. The Meta for Developers blog states pay-as-you-go starts at $1.25 input and $4.25 output per million tokens. The cached rate and the search line come from Meta's own pricing and rate limits doc. And OpenRouter's provider table lists Meta as the sole provider at the same three numbers.
| Line item | Rate | Basis |
|---|---|---|
| Input tokens | $1.25 / 1M | Per token, flat across the full 1M window |
| Cached input tokens | $0.15 / 1M | Automatic on any matched stable prefix, 88% off list |
| Output tokens | $4.25 / 1M | Includes hidden reasoning tokens |
| Web search grounding | $2.50 / 1,000 queries | Per query, charged on top of the request's tokens |
| Image, video, audio, PDF input | No separate rate published | Converted to input tokens, billed at $1.25 |
| Long-context premium | None | Same rate at 5k tokens and at 900k |
| Batch discount | Not published | No batch endpoint exists in the API reference |
| Minimum spend | None | No commitment, no platform fee, no per-seat charge |
| Free credits | $20 one-time | Per account, no published expiry |
As of 6 October 2026, Meta's pricing doc lists muse-spark-1.3, 1.2 and 1.1 on this same standard rate, and its models page recommends 1.3 for new work. A discounted Contributor tier, available on 1.3 and 1.2 only, drops the rate to $0.10 input and $0.20 output in exchange for permission to train on your prompts.
Three structural things first, before any of the numbers. They change what the rate card means.
There is no per-request fee and no per-seat fee. Obvious, maybe, until you set it next to how helpdesk vendors meter AI. Gorgias AI pricing bills per interaction, and HubSpot AI pricing bills in credits that you have to convert in your head before they mean anything.
There is no long-context surcharge. Meta's docs are explicit on this: the rate does not move as context fills up. It is a real differentiator, and I will come back to it below, once the comparison table shows what OpenAI and Google do instead.
And there is no batch tier at all. I went through Meta's API reference looking for one. Nothing. The nearest thing on offer is a limit of 600 background submissions per minute per team, and that is a throughput ceiling rather than a discount.
Four meters, and the one you budgeted for is the smallest
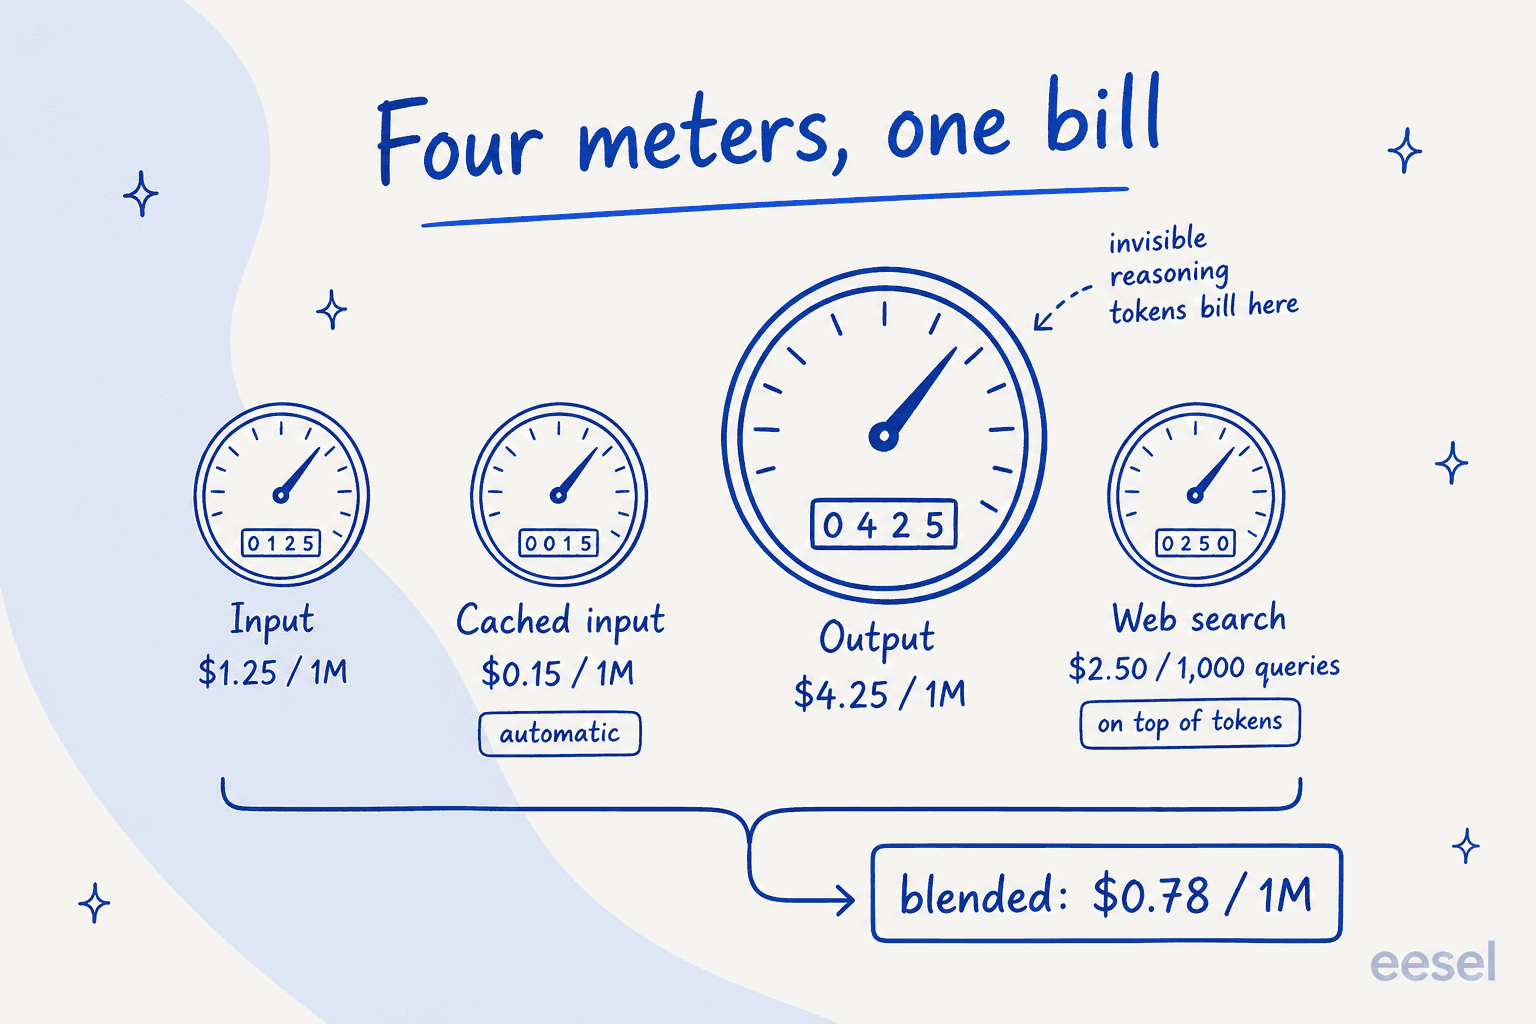
The mistake I watch engineers make with any new model API is the same one every time: read two numbers off the page, build the whole spreadsheet on those two numbers. Muse Spark 1.1 runs four meters at once. They behave differently enough that input and output rates on their own will not predict your invoice.
Put your own numbers against all four and see which one is doing the actual spending:
Meter 3 is the one that moves
Muse Spark 1.1 thinks before it answers. Meta's developer blog says so plainly enough, and the tokens spent on that thinking come back in the response as usage.completion_tokens_details.reasoning_tokens. They bill at the output rate.
Which means the $4.25 sticker is being applied to tokens you never see. How big that pile gets is set by reasoning_effort, running minimal through xhigh. One parameter, and it is a bigger lever on your bill than any choice you make about which model to call.
It also explains why Meta's own benchmark scores are hard to price against. Every single Muse Spark 1.1 result in Meta's evaluation report was run at xhigh reasoning effort, the most expensive setting the API offers. So the published capability and the cheap rate card are not describing the same configuration.
Artificial Analysis put a number on the verbosity. Across its full Intelligence Index run, Muse Spark 1.1 generated 94 million output tokens against a class median of 63 million, per Artificial Analysis, which AA calls somewhat verbose, roughly 49% above the median for its tier. Per task, that works out at about 22,000 output tokens.
Cached input is the discount that is already on
The $0.15 cached rate is 8.3x cheaper than fresh input. The part that matters more, though, is that you do not opt into it. Meta's pricing docs state the stable prefix gets cached automatically, with no flag to set and no cache key for anyone to manage.
Practitioners on Hacker News clocked this as the real story, ahead of the headline rate:
"Yeah, this is most directly comparable to xAI Grok 4.5. In both cases, directionally "opus level intelligence for haiku prices" which is a really big deal for application developers who want to include models like this in their applications. I have been testing switching out haiku and sonnet for Grok 4.5, and may give this a try too (it is quite a bit cheaper, particularly for cached)."
Someone else in the same thread ran the cache comparison out loud:
"Grok 4.5 has a relatively high $0.50 per 1M cached input token rate, compared to $0.15 on this model."
OpenRouter notes on its own model page that once prompt caching is in play, effective prices can land 60 to 80% under provider list price, depending on how much of the context repeats. And if you run a fixed system prompt with a rotating user turn on the end, that is your situation exactly.
Web search grounding is metered separately
The fourth meter is the one people miss, mostly because it is not a token rate at all. Grounding a request in web search costs $2.50 per 1,000 queries in addition to whatever tokens that request burns. Next to output it stays small at high query rates. Small is not zero, though, and it scales with how often the model decides it needs to go look something up, not with how many calls you send.
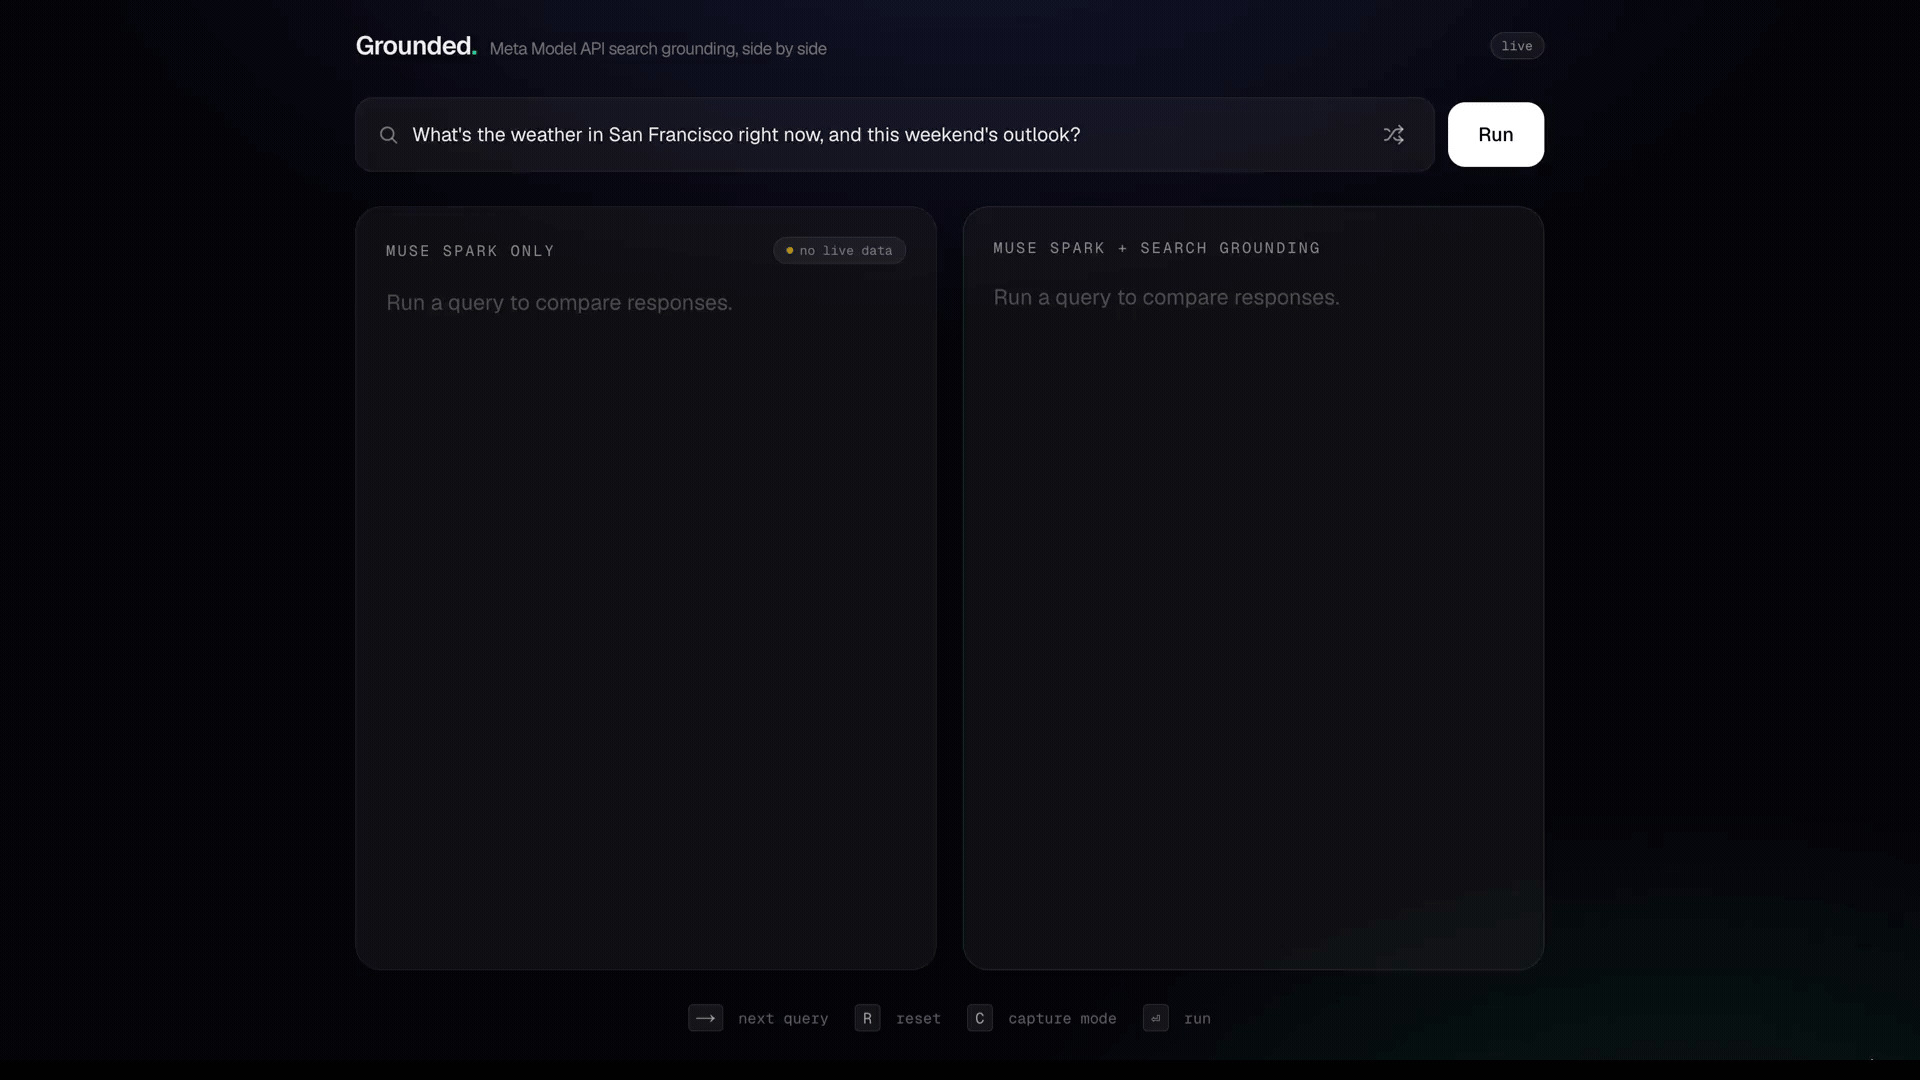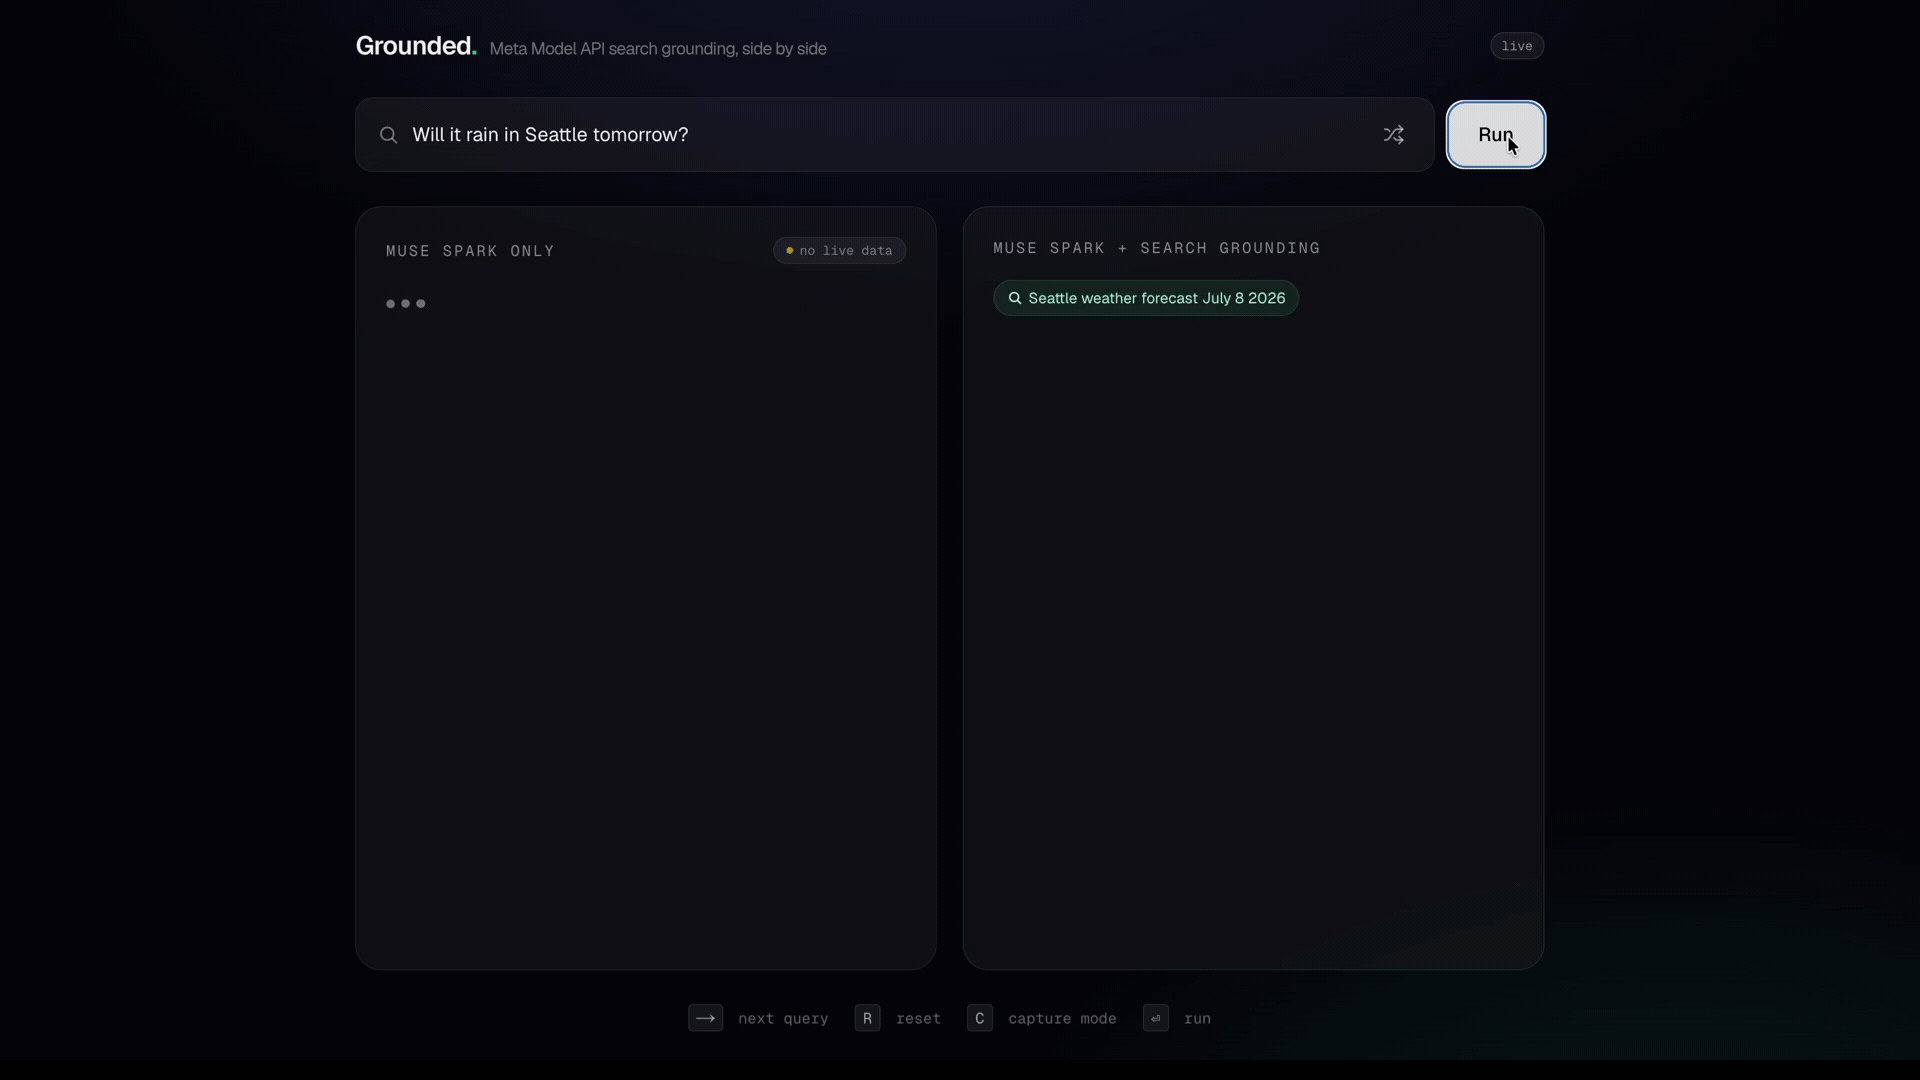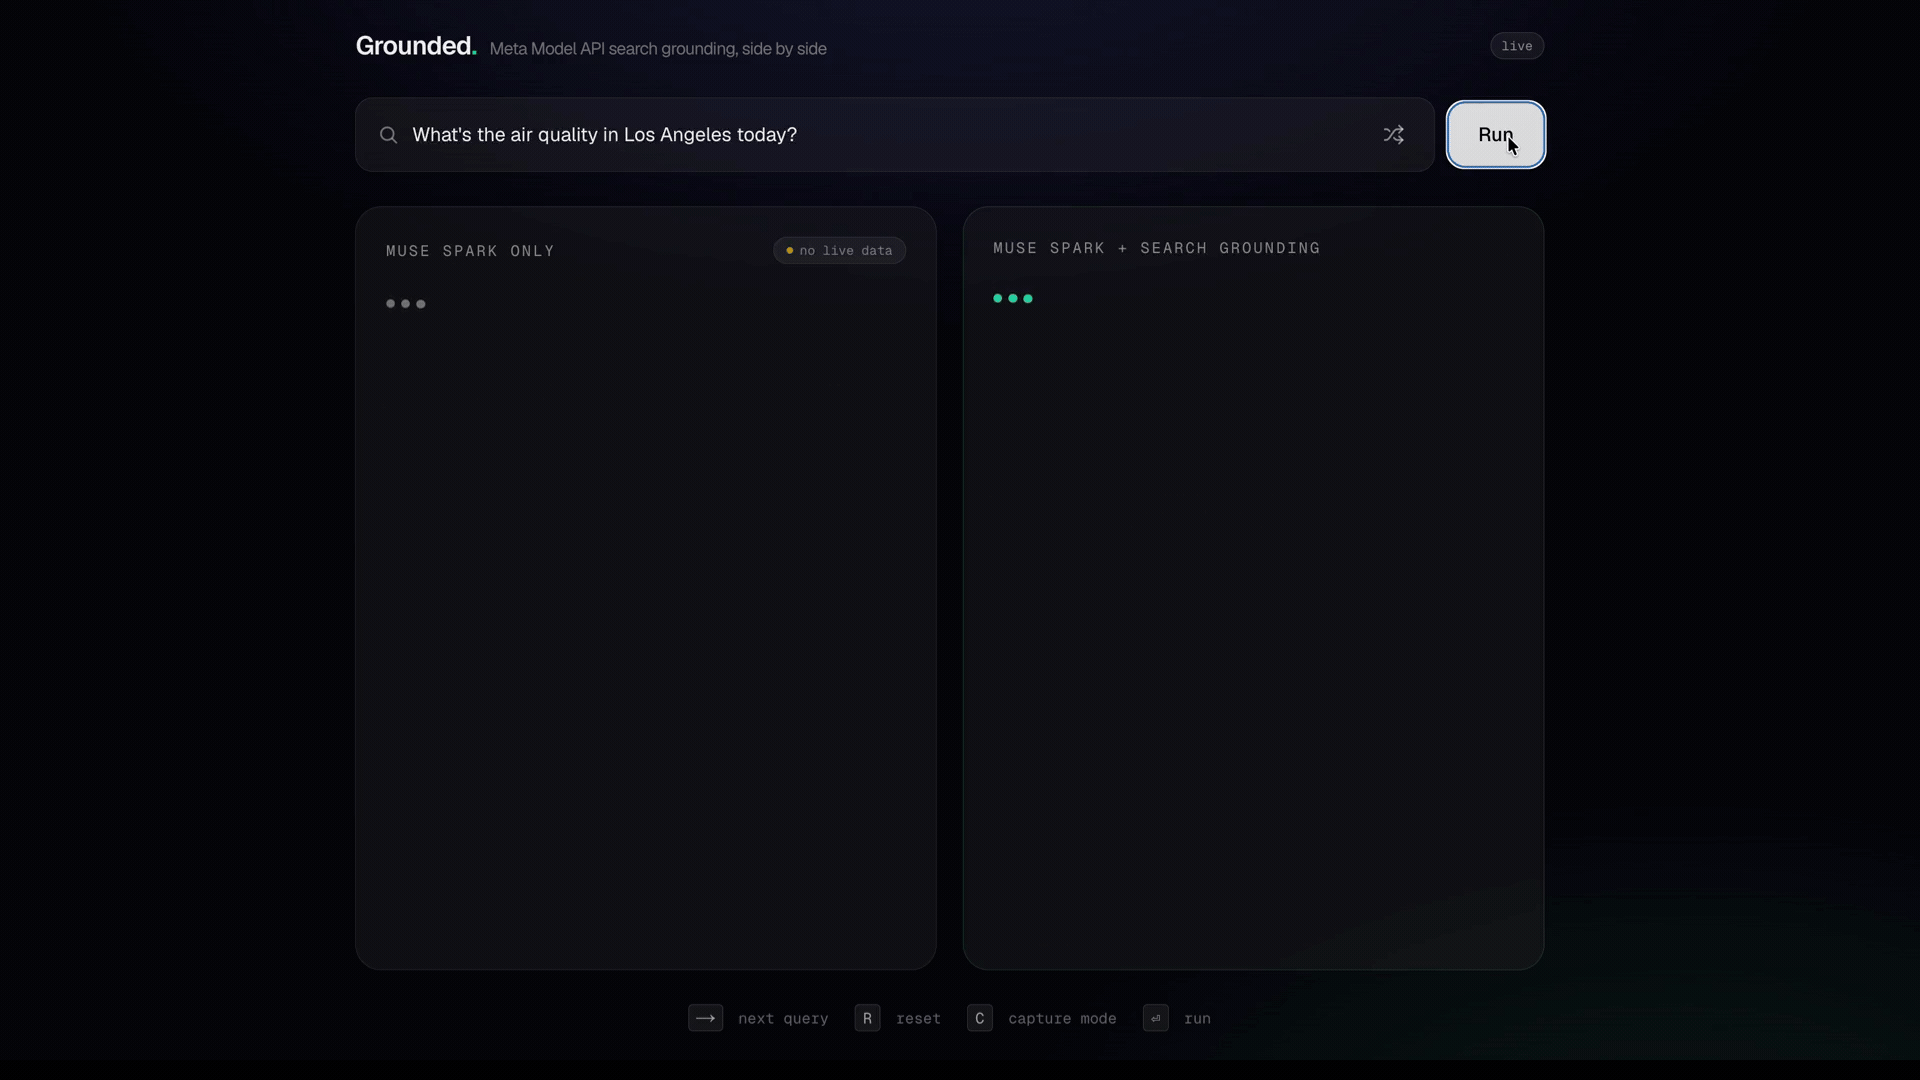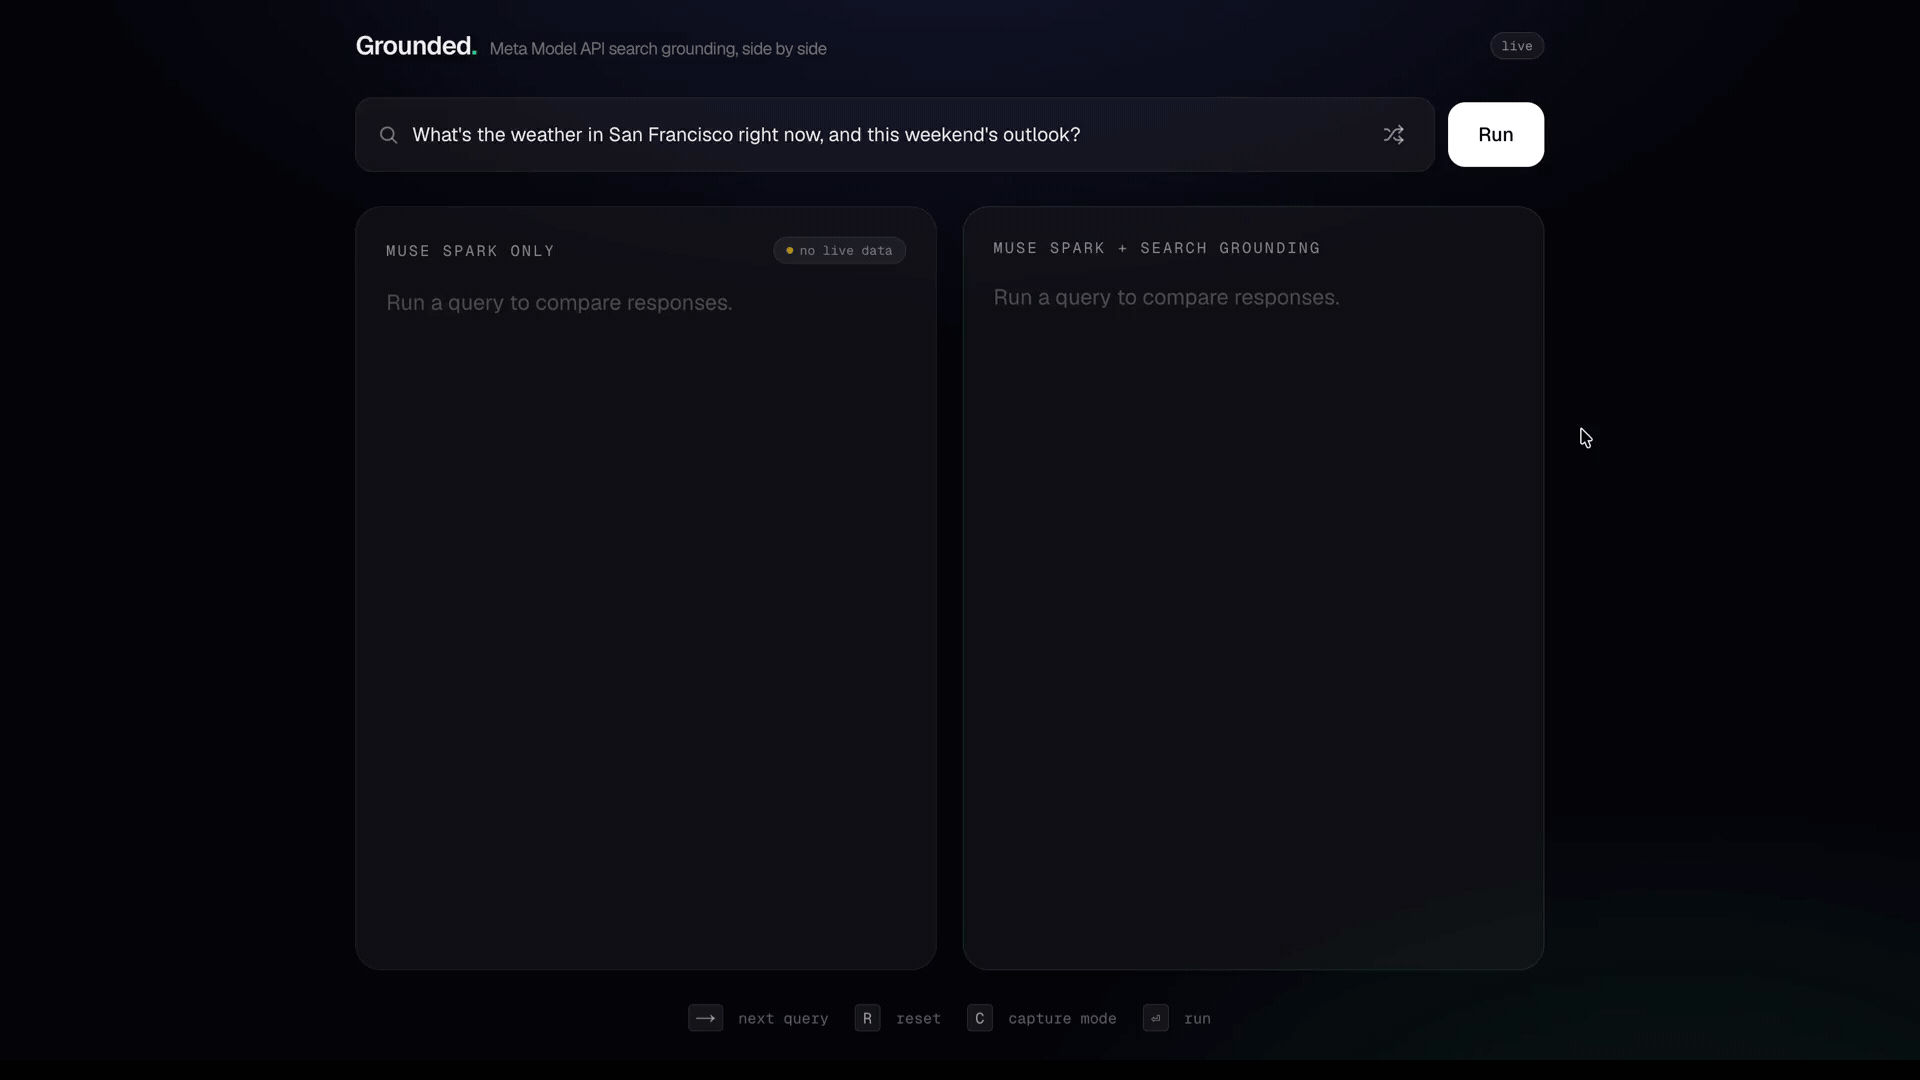
Non-text inputs work the other way round. Image, video, audio and PDF all sit in the models doc as input modalities, and not one of them carries its own published rate. They get converted into input tokens and billed at $1.25. Simpler than most vendors, sure. It also means you cannot forecast a multimodal workload until you have measured tokenization first. Image output is the exception: Muse Image bills a flat $0.01 per generated image, with its built-in search included.
The number that actually predicts your bill
Weight the three token meters the way a repeated real workload does, so seven parts cache read against two parts fresh input and one part output, and Muse Spark 1.1 comes out at $0.78 per million tokens. That is the number I would put in a budget. Not $1.25, and not $4.25.
Better still, measure whole tasks. AA does exactly that, and it is where the model looks strongest:
| Measure | Muse Spark 1.1 | Context |
|---|---|---|
| Blended rate, 7:2:1 weighting | $0.78 / 1M | Against a $1.25 / $4.25 sticker |
| Cost per Intelligence Index task | ~$0.29 | 4th cheapest of 26 frontier models charted |
| Total cost to run AA's full index | $548.07 | Claude Fable 5 needed ~$5,631 for the same run |
| Output tokens per task | ~22,000 | 12th leanest of 26, against 5,000 for the leanest |
| Intelligence Index v4.1 score | 51 | Opus 5 at max effort scores 61 |
| Output speed | 211.9 tokens/sec | 4th of 184, class median 74.0 |
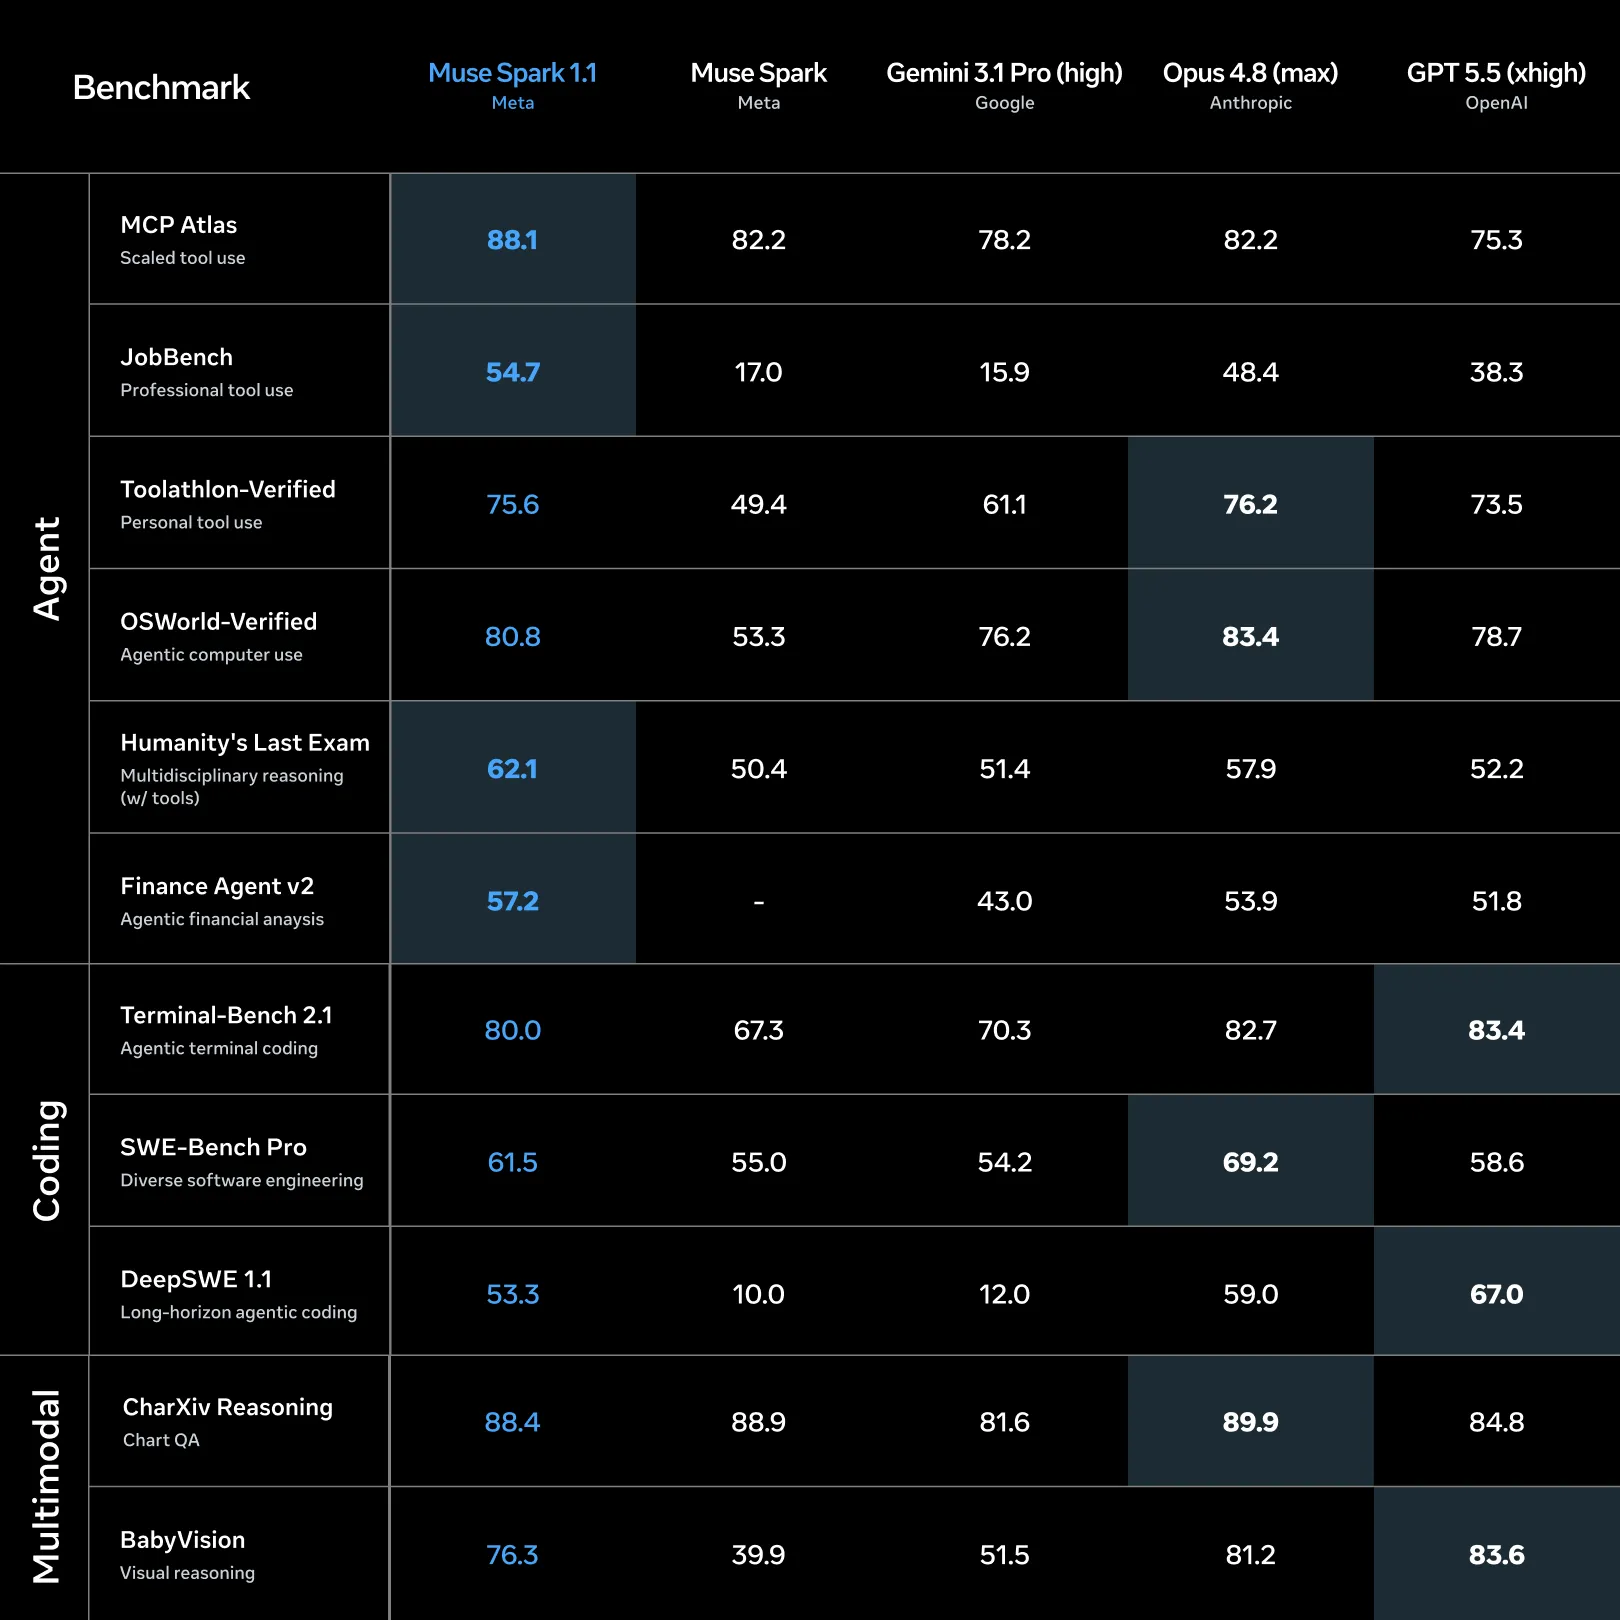
The comparison that makes the case is not the one against the top of the board. It is one row down. Muse Spark 1.1 scores 51 on AA's index at about $0.29 a task. Gemini 3.6 Flash scores 50 at about $0.56. One index point higher for roughly half the cost per task is the whole pitch, and it holds up under independent measurement, which is more than most launch claims manage.
Meta's own launch chart makes the same argument visually, and to its credit it is honest about the ceiling.
How Muse Spark 1.1 pricing compares
Every figure below comes from the vendor's own published list price per million tokens, standard tier, checked 5 August 2026.
| Model | Input / 1M | Output / 1M | Cached input | Context surcharge |
|---|---|---|---|---|
| Meta Muse Spark 1.1 | $1.25 | $4.25 | $0.15 | None |
| DeepSeek V4 Flash | $0.14 | $0.28 | $0.0028 | None, but peak-hour 2x is coming |
| GPT-5.6 Luna | $0.20 | $1.20 | Not listed | Yes |
| Gemini 3.6 Flash | $1.50 | $7.50 | Not listed | Not listed |
| GPT-5.6 Terra | $2.00 | $12.00 | Not listed | Yes, $4 / $18 above threshold |
| Claude Sonnet 5 | $2.00 | $10.00 | Not listed | None |
| Gemini 3.1 Pro Preview | $2.00 | $12.00 | Not listed | Yes, $4 / $18 above 200k |
| Kimi K3 | $3.00 | $15.00 | $0.30 | None |
| Claude Opus 5 (legacy; Opus 5.5 lists $4 / $20) | $5.00 | $25.00 | Not listed | None |
| GPT-5.6 Sol | $5.00 | $30.00 | Not listed | Yes, $10 / $45 above threshold |
Two footnotes in there decide more than the ordering does.
Sonnet 5's $2/$10 is now standard. Anthropic's 10 August 2026 release note cancelled the planned 1 September step up to $3/$15. So Sonnet 5 output costs about 2.4x what Muse Spark 1.1 output costs.
GPT-5.6 tiers by prompt size. Cross the short-context threshold and Sol jumps to $10 input and $45 output, with Terra going to $4 and $18. Gemini 3.1 Pro pulls the same move above 200k tokens.
Muse Spark 1.1 publishes one flat rate the whole way to a million. For a long-context agent workload that is worth more than a small difference in the base rate, easily. The full lineups sit in every OpenAI model if you want them side by side.
Not everyone over on Hacker News was impressed. Two lines worth keeping in view:
"this is not subsidizing. this is way too expensive for a no-name model."
"The GLM 5.2 hype was blowing way before this. Neither xAI nor Meta have really made a difference in a different way - similar results / similar pricing (to GLM 5.2)."
Both are fair points. Muse Spark 1.1 is priced competitively inside a cohort that already exists, and it is not undercutting that cohort.
Rate limits are the cost ceiling nobody reads
The rate card tells you what a token costs. Rate limits tell you how many of them you are allowed to buy, and for an agent workload that second one is the harder constraint.
| Tier | Requests / min | Tokens / min |
|---|---|---|
| Standard | 3,000 | 4,000,000 |
| Contributor | 100 | 3,000,000 |
Per Meta's pricing and rate limits doc, plus 600 background submissions per minute per team. There are details sitting underneath that table which matter more than the table:
- The Contributor tier's shape is unusual. Its token ceiling sits at 75% of Standard's, while its request ceiling is 30 times lower. A hundred requests a minute with 3M tokens means it suits a handful of very large calls, not a chatty agent loop hitting the API hundreds of times a minute.
- Limits are per team, not per key. Meta's docs spell out that multiple keys inside one team all share the same quota. So the usual trick of fanning out across keys buys you nothing here.
- Quota is observable. Every successful response carries
x-ratelimit-remaining-tokensandx-ratelimit-remaining-requests, which lets you back off against real numbers instead of guessing at them.
What Meta has not published
Being honest about the gaps beats filling them in with guesses. So here is what I could not find on any Meta-owned page.
No batch discount. Meta's two main rivals both list a 50% batch tier. Meta lists nothing at all, and there is no batch endpoint sitting in the API reference to discount in the first place.
No per-modality rates. Image, video, audio and PDF are all supported inputs, none of them with a published per-unit price. They bill as input tokens, and that is fine right up until you need to forecast a video workload.
No expiry on the $20. Meta's developer blog confirms the free credit as one-time per account. No page anywhere states when it lapses.
Data retention took a thread to establish. It came up on Hacker News as a complaint first, then resolved into a real finding, which is the most useful kind of source there is:
"Where is the data retention policy information for paid API per-token uses? Every other provider has one and makes it clear how they handle your data. A quick look doesn't show one for this new offering."
"Paid prompts are not used for training. Data retention is not entirely clear, they will keep it if they think you're breaking the rules, but it's not clear how long they keep it if they don't think you're breaking the rules."
No consumer price for Meta One. Meta's help pages confirm a paid consumer subscription exists in limited testing, and they name the Meta One tiers as Plus, Premium, Advanced, Expert and Max. No dollar figure on any of them, anywhere. So any consumer price you see quoted elsewhere, treat as unverified. Consumer Meta AI itself stays free, and Muse Spark 1.1 is already exposed there in Thinking mode at no stated charge, which is worth knowing before you pay for API access purely to evaluate the model.
The gate you hit before the bill
At launch, this pricing was reachable only from the United States. Meta's launch post put the Meta Model API in public preview for US developers, and OpenRouter carried a country restriction on its model page. Meta's product page now says "expanded global access" and I found no country list, so check your own account.
Developers ran straight into it:
"Tried to get access to the API, apparently the model API is not available in my region..."
"I don't know where I need to sign up to try it out. What is pricing? Is it API or subscription, what?"
There is no waitlist here, and no approval step either. Meta's quickstart is just dashboard, API keys, create key. The API is OpenAI SDK compatible, so swapping a base URL covers most of the integration work. At launch the eligibility limit lived on the marketing pages instead of in the docs, which is why people only found out about it after signing up.
Cost per million tokens is the wrong unit for a support team
Here is where I should be straight about who this rate card is for. Building a coding agent or a research tool? Then $0.78 blended is a good deal, and the Muse Spark 1.1 review is where to go for whether the capability clears your bar.
But if you are trying to work out what an AI costs to answer your customers, tokens are the wrong denominator entirely. The unit is a resolved ticket, and the spread on that unit is enormous. One e-commerce account I have real numbers on was running about 700 tickets a week at roughly $1.07 a ticket. eesel's own plan starts at $299 a month for 500 credits (one credit per ticket or chat, about $0.60 a ticket at that size) with no platform fee, and eesel pricing is right there to check it against. Same class of model underneath. Nearly 2x of spread, driven entirely by what sits around the model.
And the gap between a model being right and a model being shippable is wider than any price difference. A German jewelry retailer running about 1,000 tickets a month on Zendesk and Shopify put eesel through a cross-validated trial on real traffic. What came back: 93% triage accuracy, 100% spam detection with zero false positives on the 22% of the inbox that was spam, 88% draft directional accuracy, and only 12% of drafts sent as-is, with a 7% factual error rate.
Read those last two numbers together. Directionally right 88% of the time, shippable 12% of the time. When I broke down why agents were rewriting the drafts, about 65% came down to length and tone, about 20% needed data nobody had connected yet like ERP and logistics, and only about 5% was eesel being factually wrong. Model quality was 5% of the problem. The rest was context, voice and integration depth, which is exactly the part a cheaper token rate does nothing about. That is the argument in RAG vs LLM and in answering incorrectly, and the fix sits closer to agent coaching than to a model upgrade.
The other thing a rate card cannot price is knowing when to say nothing at all. A CX lead at a DTC supplements brand, running about 7,000 Gorgias tickets a month, put it better than I can:
"The AI will never be able to answer 100% of the questions, but if it tries and just answers 'sorry I don't know this,' I cannot go and check all my 7,000 tickets to see if the AI actually made a good answer, then the point is a little bit gone. I need an AI who is only handling the tickets that it's confident to handle and all the other ones, leave them alone."
That is a confidence threshold plus an escalation path. It is not a model. It is product work, and it is the same reason AI handoff and transfer to human take up more of my time than model selection ever does.
Building it yourself on the Meta Model API is a real option, and I am not going to pretend otherwise. Some teams have left eesel to build directly on a frontier API, and it worked out for them. The honest version of that trade, though, came from an engineering lead at a Bitcoin-ATM company with a 300-article Confluence and Telegram knowledge base, who went the other way:
"We could try to write our own LLM application but we didn't want to invest our time into that. We wanted something that we would not have to maintain."
The model was never the hard part. Maintenance was the hard part. If you want that fork in the road spelled out properly, Anthropic vs OpenAI APIs and AgentKit pricing both cover what the build path really costs once the parts that are not tokens get counted.
Try eesel on your own tickets
Landed here budgeting a support AI rather than an API experiment? Skip the token math. eesel's AI helpdesk agent reads the help centre and the past tickets you already have, and starts at $299 a month for 500 credits (1 credit per ticket or chat), with no platform fee and a free plan of 100 credits.
It plugs into whichever helpdesk you already run, Zendesk, Freshdesk and Gorgias included, so nobody on the team has to learn a new tool to get value out of it.
Knowledge sources connect the same way. A help centre living in Confluence becomes a source on day one, not a migration project.
Before it answers anyone at all, it simulates against your own historical tickets, so the resolution rate and the cost show up against your real traffic first. That is the step that turned an 88% and 12% trial into something worth shipping. A gig-economy driver app on Zendesk ran a 7-day trial, and Gridwise resolved 73% of tier-1 requests in the first month.
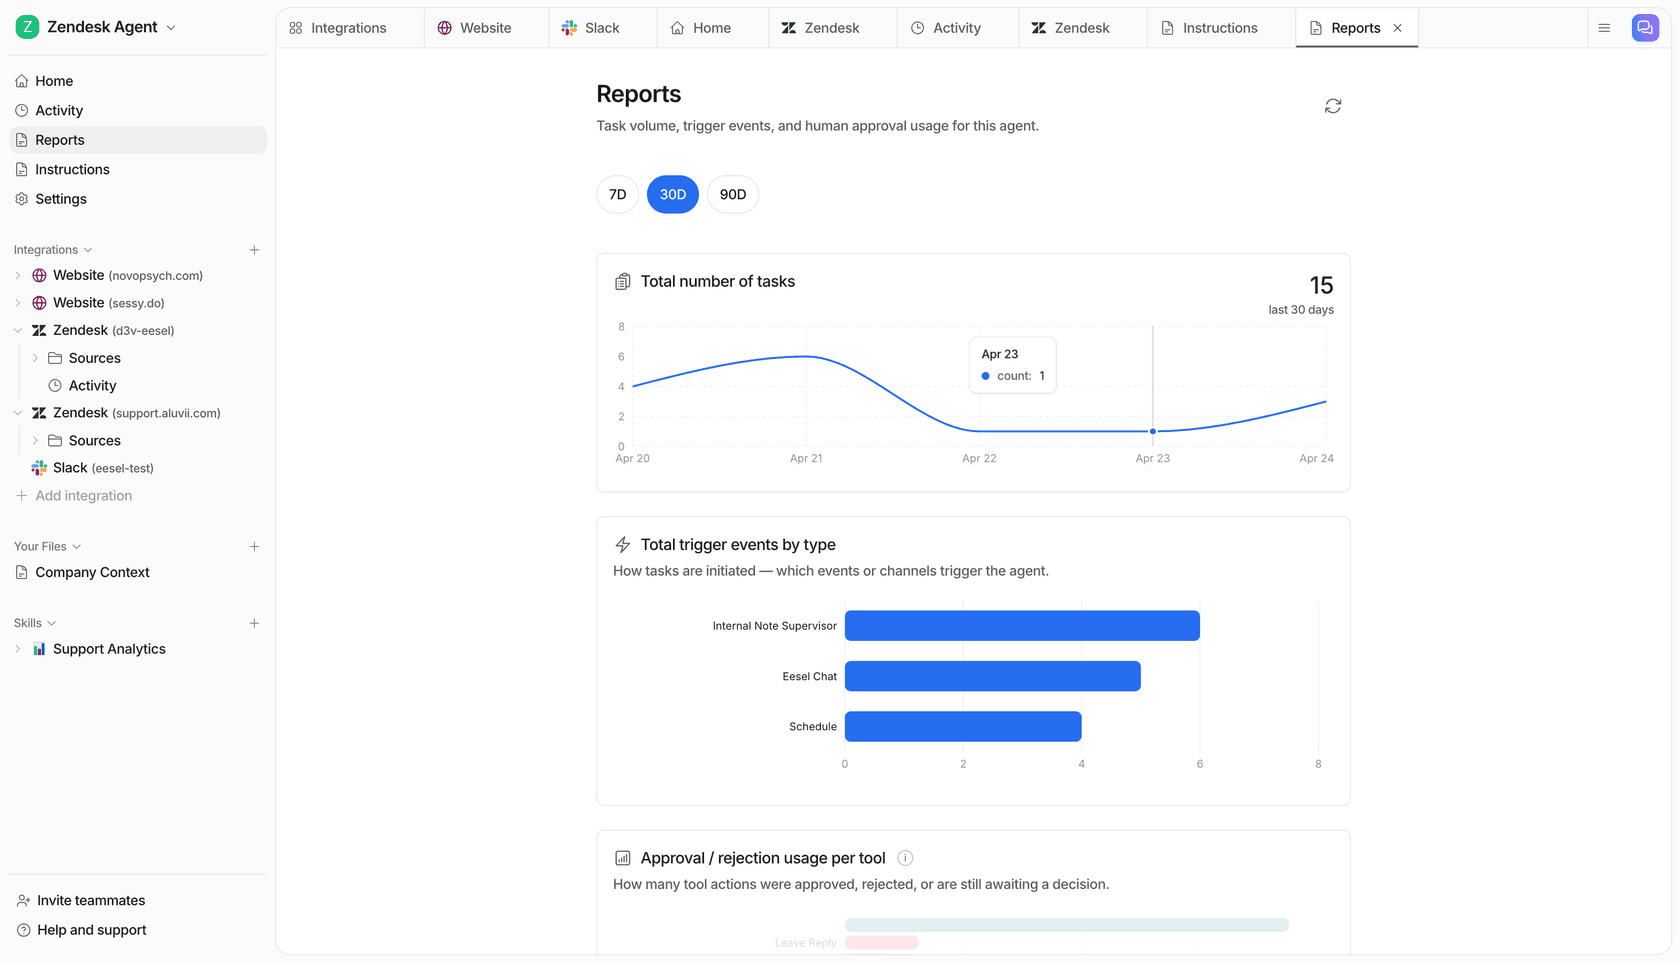
Free to try, and the numbers land on your own queue before you commit to anything. If you would rather compare tools first, the roundups to start from are best AI helpdesk software and best AI agent, while AI customer service cost does the per-resolution math properly.
The verdict on Muse Spark 1.1 pricing
$1.25 and $4.25 are real, verified, and not the numbers that will decide your invoice. Plan against $0.78 blended and $0.29 a task. Assume the caching discount is already working for you, and treat reasoning_effort as the pricing dial it actually is. The flat rate across a million tokens is a real advantage over OpenAI and Google, the missing batch tier is a real gap, and the launch-era US-only gate is the constraint to confirm for your own account before any of the rest of it matters.
For a support workload, keep the frame straight. Token price is one input into cost per resolved ticket. It is not the biggest input.
If that is your question, there are deeper reads for each piece: support ticket automation for the outcome, ticket triage for the mechanism, then resolution rate for measuring whether any of it worked.
And when finance asks you to justify the spend, the comparison they will actually want to see is AI vs human cost.