
Anthropic API pricing: standard model rates
Selected current rates, checked 8 September 2026, in USD per million tokens. This table covers standard first-party API usage, not every retired model, deployment route, or negotiated agreement. Check Anthropic's pricing reference before committing a budget.
| Model | Input | Output | Cache read |
|---|---|---|---|
| Claude Fable 5.1 | $10 | $50 | $0.25 |
| Claude Fable 5 | $10 | $50 | $1 |
| Claude Opus 5 | $5 | $25 | $0.50 |
| Claude Sonnet 5 | $2 | $10 | $0.20 |
| Claude Sonnet 4.6 | $3 | $15 | $0.30 |
| Claude Haiku 4.5 | $1 | $5 | $0.10 |
Sonnet 5's $2/$10 rates remain standard after August 2026; the previously announced September increase did not happen. Fable 5.1's cache-read rate is lower than Fable 5's, so a blanket “cache reads cost 10%” rule is no longer correct.
I would not pick a production model from these numbers alone. Run the same evaluation set through the candidates and count acceptable results. A lower rate can lose its advantage if your application needs more attempts or substantially more human correction. See the model selection guide for the broader decision.
Calculate the token bill without double-counting
Separate usage into categories before applying rates:
Token cost =
  uncached input tokens × input rate
  + cache-write tokens × cache-write rate
  + cache-read tokens × cache-read rate
  + output tokens × output rate

Divide by 1,000,000 when rates are quoted per million tokens.
Add separately billed tools and services afterward.
Use the categories reported by the API, not the total prompt length copied into every line. A token served from cache should not also be charged as ordinary input in your spreadsheet.
For a hypothetical uncached Sonnet 5 request containing 8,000 input tokens and 900 output tokens:
- Input: 8,000 ÷ 1,000,000 × $2 = $0.016.
- Output: 900 ÷ 1,000,000 × $10 = $0.009.
- Total: $0.025, before any additional services.
At 50,000 identical requests, that is $1,250. It is a token estimate, not a promise that 50,000 customer requests will fit that shape.
An agent handling one customer request might inspect a record, ask another question, and call the model again with a longer conversation. Capture every billable call associated with that task. If you measure only its final response, your estimate will miss earlier work.
Prompt caching: include the write, not just the hit
Anthropic's prompt caching documentation describes separate creation and reuse costs. A five-minute cache write costs 1.25 times the base input rate; a one-hour write costs twice the base rate. Reads are discounted, with model-specific rates shown above.
For the models using a 0.1-times read rate, the five-minute cache pays off after one reuse. The one-hour cache needs two reuses. This comparison applies to the cached prefix, not the whole request.
Here is an illustrative Sonnet 5 calculation for a 10,000-token prefix reused across ten requests within the cache lifetime:
| Prefix processing | Calculation | Cost |
|---|---|---|
| No caching | 10 × 10,000 × $2 / million | $0.200 |
| Five-minute write | 10,000 × $2.50 / million | $0.025 |
| Nine cache reads | 9 × 10,000 × $0.20 / million | $0.018 |
| Cached total | Write plus reads | $0.043 |
That saves $0.157 on the prefix. Unique user text and generated output still need their own lines.
Caching also has minimum prompt lengths. A marked prefix below the model's threshold can be processed without caching and without an error. Check the response's cache creation and cache read fields. Two zeros are a reason to investigate, not evidence of free processing.
A high cache-hit percentage is only useful alongside the amount of input eligible for reuse. If output dominates the bill, a large input discount may produce a modest overall saving.
Batch processing: lower rates for work that can wait
The Batch API discounts input and output tokens by 50% and supports asynchronous processing. Batches can take up to 24 hours; the documented limits are 100,000 requests or 256 MB per batch.
That fits a document backfill or offline classification job. It is a different fit from answering a live customer who is waiting for a reply.
For an illustrative backfill of 200,000 documents on Sonnet 5, each with 5,000 input and 800 output tokens:
| Processing route | Input cost | Output cost | Total |
|---|---|---|---|
| Standard | $2,000 | $1,600 | $3,600 |
| Batch | $1,000 | $800 | $1,800 |
Assumptions: no caching, no additional tools, and every document successfully processed once. Split the workload into batches that satisfy both count and size limits.
Batch results need inspection. Only successfully processed requests are billed; failed, canceled, and expired results still leave work for your application to handle. Budget for successful retries and do not equate “batch submitted” with “backfill completed.”
Batch and caching can combine, but a cache hit is not guaranteed merely because requests share text. Measure actual usage when validating the estimate.
Effort changes usage, not the price of a token
The effort setting affects how much work Claude puts into a response. The default is high. Supported levels vary by model, and effort is a behavioral signal rather than a hard token budget.
I would test a lower setting on routine tasks and keep it only if the output still meets the acceptance criteria. There is no universal percentage saving to apply across all prompts.
Two details matter for budgeting:
- On Opus 5, changing effort does not reliably shorten the visible answer. Request a length limit separately when that is the requirement.
- Changing top-level effort invalidates cached prefixes. Some models, including Opus 5 and Fable 5.1, support a per-message effort change that preserves the cache; check compatibility before assuming this works everywhere.
Keep a record of model, effort, output length, retry count, and acceptance rate. Changing several settings at once can make it difficult to identify why the cost moved.
Additional costs and deployment choices
The main rate table does not cover every charge. Anthropic documents separate server-side tool costs and pricing modifiers. US-only inference adds a 1.1-times token multiplier on supported models; fast mode on Opus 5 and Opus 4.8 uses $10 input and $50 output per million tokens.
Before estimating a tool-using application, identify which operations happen inside the model service and which happen in your infrastructure. Your own search index, database, monitoring, and third-party APIs may produce separate bills.
For the provider side, check the applicable tool pricing and deployment route. A first-party API estimate should not be copied into a cloud marketplace budget without checking its terms.
Avoid treating a spend limit as a complete operational plan. Decide who gets alerted, what work stops, and how customers receive help if capacity is unavailable. Your support cost model needs that fallback alongside the software line.
Compare the same job before comparing API and product costs
A classifier that assigns one label is not equivalent to a teammate that reads a ticket, checks knowledge, drafts a response, and hands off an exception. Both may be useful, but they are different scopes.
For a fair build-versus-buy evaluation, define a representative task and compare the complete process:
| Cost or responsibility | Custom API workflow | Ready-made support teammate |
|---|---|---|
| Model work | Meter every request and retry | Check the product's task definition |
| Knowledge | Build and maintain retrieval | Verify connected sources and freshness |
| Helpdesk actions | Implement API access and checks | Verify the integration's supported actions |
| Review | Include human correction time | Include approval and handoff time |
| Operations | Hosting, monitoring, and maintenance | Configuration, monitoring, and vendor limits |
| Outcome | Confirm the customer problem is solved | Apply the same acceptance criteria |
The point is not that one side always wins. A narrow, stable internal job may justify an API build. An existing support product may reduce the setup and maintenance needed for a broader workflow. Measure the parts your team would actually own.
This is where eesel's support teammate becomes a relevant comparison. It provides the support workflow, while the CLI gives people and software a way to operate it.
Evaluate support costs through eesel CLI
eesel CLI lets you use the same eesel teammate and workspace from your terminal that your team uses in the dashboard. Scripts and coding agents can drive it too, using JSON output to inspect results.
That matters to an API-focused reader: choosing a ready-made support teammate does not mean every setup or review step must be a manual dashboard task. You can inspect its configuration and run bounded work from your existing terminal workflow.
Check billing and configuration first
With Node.js 18.17 or newer, use the documented npm package. For an existing eesel workspace:
npx @eesel/cli login
npx @eesel/cli whoami
npx @eesel/cli agents
npx @eesel/cli billing
npx @eesel/cli status --agent AGENT_ID
npx @eesel/cli automations --agent AGENT_ID
Replace AGENT_ID with the intended agent's ID. Confirm the workspace identity before interpreting the billing result.
The billing command shows live billing state and is read-only. It does not pull your Anthropic invoice or produce a complete historical cost forecast. Inspect automations as well: the amount of work routed to a teammate is part of the budget.
According to eesel's pricing docs, the Teammate plan starts at $299 a month for 500 credits, and 1 credit covers one ticket or chat, however many messages it takes. Blog drafts are $4 each, and questions asked in the dashboard are mostly free. A credit covers the interaction, not every message, and is not a guarantee of successful resolution.
The monthly price is fixed, with no platform fee or per-seat fee. If you run out of credits, agents pause until they reset, unless you turn on overage with a monthly cap you set ($0.80 per extra credit). Set an appropriate cap and a human fallback in workspace billing settings before a rollout.
Run one defined evaluation task
Use a controlled workspace with suitable action permissions. Prepare a local support-evaluation.md file containing an approved policy and a fictional customer case. Do not upload customer secrets simply to make an example realistic.
npx @eesel/cli files upload ./support-evaluation.md --agent AGENT_ID
npx @eesel/cli instructions --agent AGENT_ID
npx @eesel/cli new --name "support-cost-evaluation" --agent AGENT_ID
npx @eesel/cli chat 'Using support-evaluation.md, draft a response to the fictional customer case. Identify missing facts and explain when human help is needed. Do not send messages or change records.' --agent AGENT_ID
npx @eesel/cli activity --agent AGENT_ID
Uploading supplies knowledge; it does not set standing rules or grant integration permissions. Reading instructions lets you inspect the agent's existing rules before the chat. The draft-only prompt states your intent, but it is not an enforced permission boundary. A real chat can invoke enabled tools.
Review the answer and activity, including any human work needed to make the response usable. A fictional case can test policy reasoning; it does not prove that a live helpdesk lookup or customer-facing action succeeds. Test those separately with authorization.
The CLI's --dry-run option previews the server call a write would make without sending it. It does not simulate the agent or predict the charge. The CLI reference documents the supported commands and their options.
Keep the billing accounts separate
eesel CLI is not an Anthropic API proxy. Work performed by eesel follows eesel's billing model. If a separately billed coding agent operates the CLI, account for that tool's usage as well. Neither invoice should be assumed to include the other.
For your comparison sheet, record the defined task, observed usage, answer quality, and human review time. Compare that with the complete custom API workflow, not only its cheapest token call.
Try eesel CLI for a scoped support workflow
If you are pricing Anthropic to build support automation, start with one queue or topic. Measure the custom build and the ready-made teammate against the same expected result.
eesel CLI lets you inspect connections, instructions, billing, and automation scope without leaving the terminal. The work remains available in the dashboard, so your support team can review it there rather than adopting a separate technical tool.
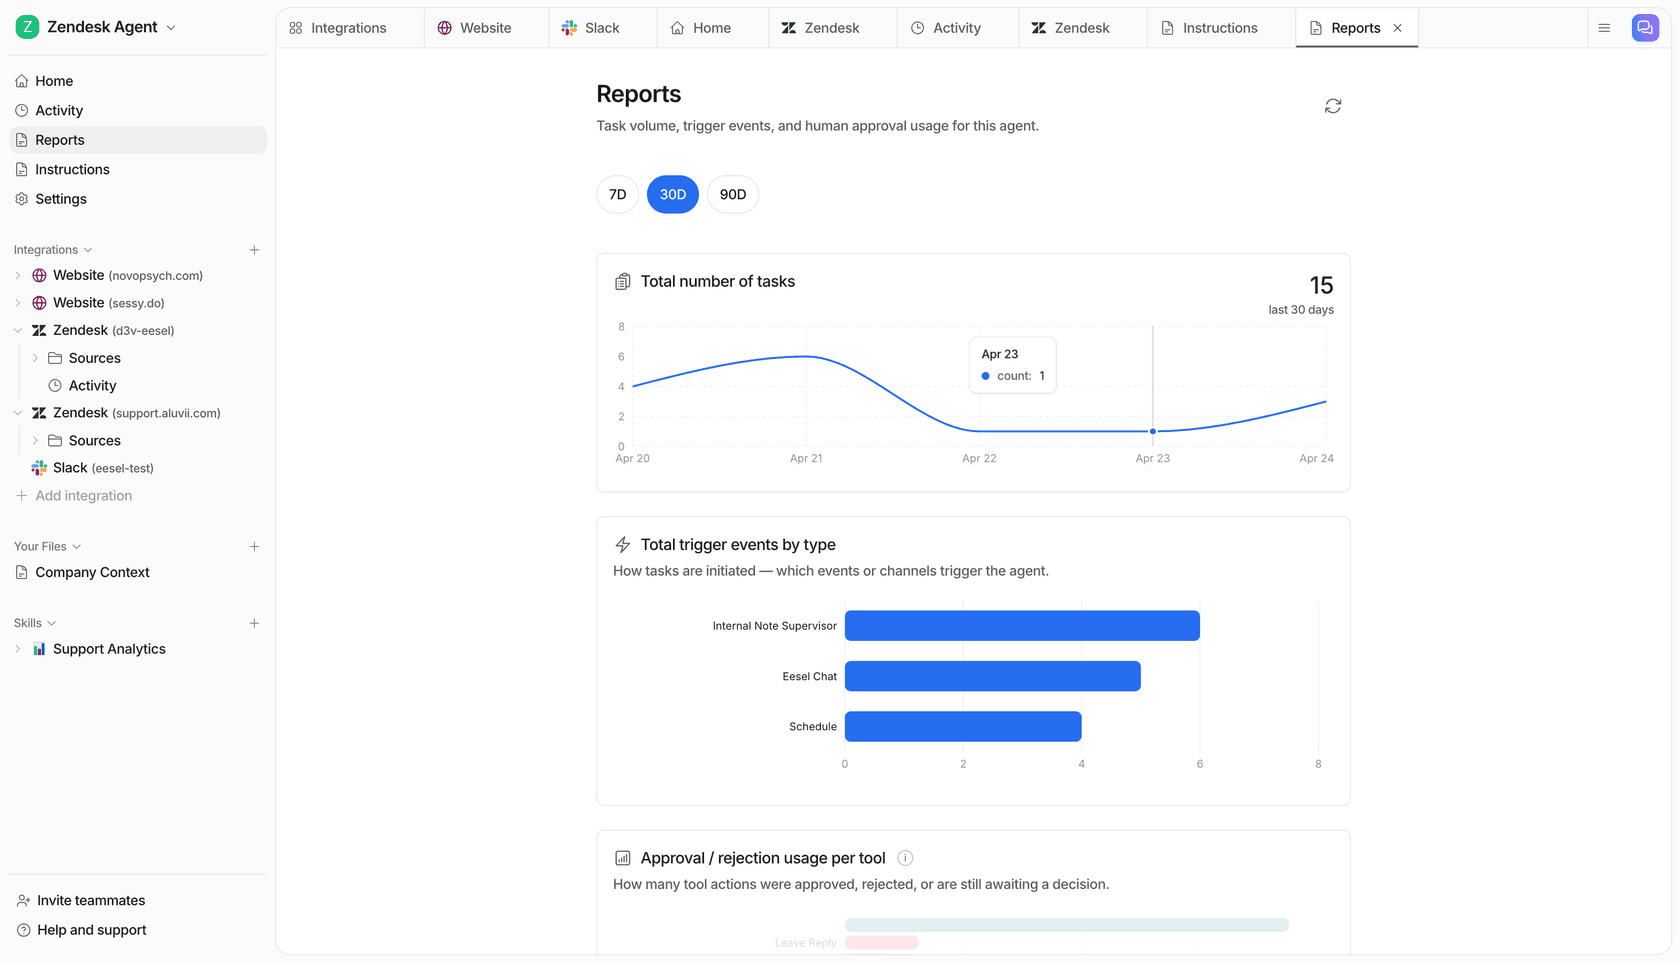
Try eesel with a defined support task, then compare the observed result and operating cost before widening the rollout.